Our verdict: Anthropic is the best primary API for quality production traffic. OpenAI is the best for breadth, Groq is the fastest, and Together AI is the best home for open models and fine-tuning.
If you're shipping a product on an LLM in 2026, you aren't picking one provider. You're picking a primary and a fallback, because one provider's outage shouldn't take your product offline for four hours.
 Anthropic
 OpenAI
 Groq
 Together AI
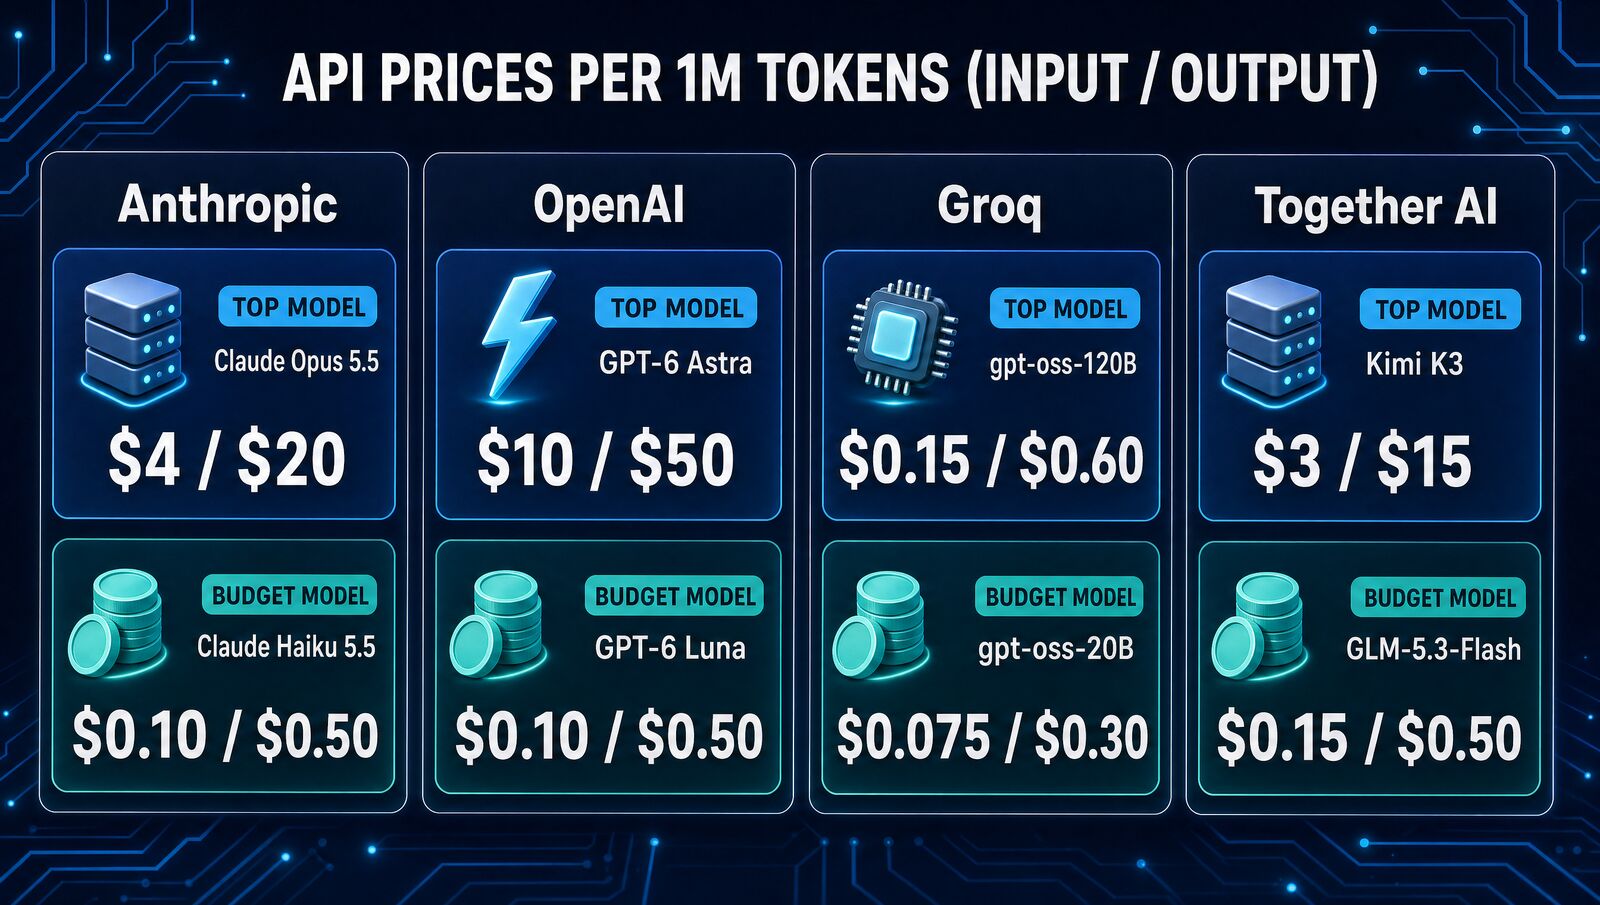
Top models run from cents to $50 per million output tokens. Every budget model here costs under a dollar.
The 4 APIs at a glance
Anthropic- Sonnet 5.5 at $2 / $10 for everyday traffic
- Up to 1M tokens, no long-prompt surcharge on Opus or Sonnet
- Cached reads at a tenth of the input price
The catch: text output only.
OpenAI- Text, image, realtime voice and transcription
- GPT-6 Astra for science and computer automation
- GPT-6 Luna at $0.10 / $0.50
The catch: prompts past 272K tokens cost more.
Groq- About 1,000 tokens a second on gpt-oss-20B
- Runs on its own LPU chips
- gpt-oss-120B at $0.15 / $0.60
The catch: open models only, short menu.
Together AI- Widest open-model catalog here
- Fine-tuning for Llama and Qwen
- Dedicated H100s from $5.49 per GPU-hour
The catch: no Claude or GPT models.
Prices compared
Prices checked October 23, 2026, on each company's own pricing page.
| Provider | Top model (in / out per 1M tokens) | Budget model (in / out per 1M) | Best for | Catch |
|---|---|---|---|---|
| Anthropic | Claude Opus 5.5: $4 / $20 | Claude Haiku 5.5: $0.10 / $0.50 (prompts up to 100K tokens) | Quality production traffic, coding agents | Text output only |
| OpenAI | GPT-6 Astra: $10 / $50 | GPT-6 Luna: $0.10 / $0.50 | Breadth: text, image, audio, realtime | Prompts past 272K tokens cost more |
| Groq | gpt-oss-120B: $0.15 / $0.60 | gpt-oss-20B: $0.075 / $0.30 | Speed: about 500 to 1,000 tokens/sec | Open models only, short menu |
| Together AI | Kimi K3: $3 / $15 | GLM-5.3-Flash: $0.15 / $0.50 | Open-model breadth, fine-tuning, dedicated GPUs | No Claude or GPT models |
What each one offers
| Feature | Anthropic | OpenAI | Groq | Together |
|---|---|---|---|---|
| Claude or GPT models | ✓ | ✓ | ✗ | ✗ |
| Open-weight models | ✗ | – | ✓ | ✓ |
| Prompt caching discount | ✓ | ✓ | – | ✓ |
| Image generation | ✗ | ✓ | ✗ | – |
| New fine-tuning | – | Winding down | – | ✓ |
| Dedicated GPUs | – | – | – | ✓ |
– means the company hasn't said.
Anthropic: best for quality production traffic
If your product depends on Claude-quality output (coding agents, long-context analysis, customer-facing reasoning), start here. Claude Opus 5.5 at $4/$20 tops our September frontier ranking, and Sonnet 5.5 at $2/$10 comes close for half the price.
Prompts run up to 1M tokens with no long-prompt surcharge on Opus or Sonnet, and Opus costs 40% of GPT-6 Astra. The trade-offs: rate limits on smaller account tiers can sting on burst traffic, and there's no image generation.
OpenAI: best for breadth
OpenAI covers the most ground under one key: the GPT-6 family for text (Astra at $10/$50, Sol at $2/$10, Luna at $0.10/$0.50), plus image generation, realtime voice, transcription and embeddings. GPT-6 Astra is strongest on science-heavy work and computer automation.
For routine traffic, Sol is the sensible default, though it trails Claude Opus 5.5 in independent testing. Astra is the priciest frontier model here, and requests past 272K input tokens bill at $20/$75. OpenAI is also winding down its fine-tuning platform, so don't plan new custom models there.
cache_control to the prefix you reuse. It's a small code change.Groq: best for low latency
Groq runs open-weight models on its own LPU chips. It lists gpt-oss-20B at about 1,000 tokens a second and gpt-oss-120B at about 500, several times what you'll usually see from frontier APIs.
That speed matters for voice agents and live coding help, anywhere a user waits on streaming text. The ceiling: no Claude or GPT, and a short production menu of gpt-oss-120B, gpt-oss-20B, Llama 3.3 70B and Llama 3.1 8B.
Together AI: best for open models and fine-tuning
Together hosts the broadest open-weight catalog here, from DeepSeek V4, Kimi K3 and GLM-5.3 down to small Qwen and Gemma models. Dedicated endpoints put your model on reserved H100s from $5.49 per GPU-hour.
Fine-tuning Llama or Qwen on Together is the cheapest path to a custom model you don't host yourself. Most teams use it as a fallback for open-model traffic rather than a primary.
Which API should you use?
For the cheap tier in detail, see our cheapest AI model verdict.
The verdict
Use Anthropic as your primary, defaulting to Sonnet 5.5 with prompt caching from day one, and keep an OpenAI key warm as the fallback. Add Groq when latency is product-critical and Together when you fine-tune, because a single-provider stack is an outage waiting to happen.
FAQ
Which AI inference API is best for production in 2026?
Anthropic for quality production traffic, led by Claude Opus 5.5 at $4/$20 per million tokens and Sonnet 5.5 at $2/$10. OpenAI for breadth: GPT-6 models plus image, audio and realtime APIs under one key. Groq for speed on open models. Together for the widest open-model menu, fine-tuning and dedicated GPUs. Most teams use two: a primary frontier provider and a fast or cheap fallback.
Which API is fastest?
Groq. It runs open-weight models on its own LPU chips and lists gpt-oss-20B at about 1,000 tokens per second and gpt-oss-120B at about 500. The catch: Groq doesn't host Claude or GPT models, only open-weight ones. If your latency budget is tight and your task fits an open model, Groq wins.
Which API is cheapest?
It depends on the tier. At the bottom, OpenAI's GPT-6 Luna and Anthropic's Claude Haiku 5.5 both cost $0.10/$0.50 per million tokens, which undercuts most hosted open models. Groq's gpt-oss-20B is cheaper still at $0.075/$0.30. Together is the cheapest place to fine-tune and run a wide range of open models. Always benchmark with your actual prompts.
Should I use prompt caching?
Yes, on every API that offers it. Anthropic bills cached input reads at a tenth of the normal input price, and OpenAI also discounts repeated prefixes. Savings are biggest on workloads with stable system prompts or repeated context. On Anthropic, pass cache_control on the prefix you reuse. It's a small code change.
Do I need to multi-vendor my AI infrastructure?
For production, yes. Single-provider dependency is a real outage risk. The minimum viable multi-vendor setup is a primary provider for quality plus a fallback (often Together or Groq on open models) that your code routes to on errors.