In July, Fable 5 was the strongest cloud LLM for hard agentic coding and reasoning. That's no longer the pick. Claude Opus 5.5, released September 22, now matches or beats Fable on most tasks for $4/$20 instead of $10/$50. Fable is now Fable 5.1, and it's mainly worth paying for brand voice and long-form drafting.
When Anthropic launched Claude Fable 5 on June 9, 2026, it created a new tier above Opus and called it "Mythos-class." We lined it up against the rest of the frontier on published benchmarks and pricing: GPT-5.4 and 5.5, Gemini 3 Ultra and xAI's Grok 4 family.
 Claude Fable 5.1
Claude Opus 5.5
Claude Sonnet 5.5
 GPT-6 Astra
 Gemini 4 Argon
 Grok 4.7
How Fable 5 scored at launch
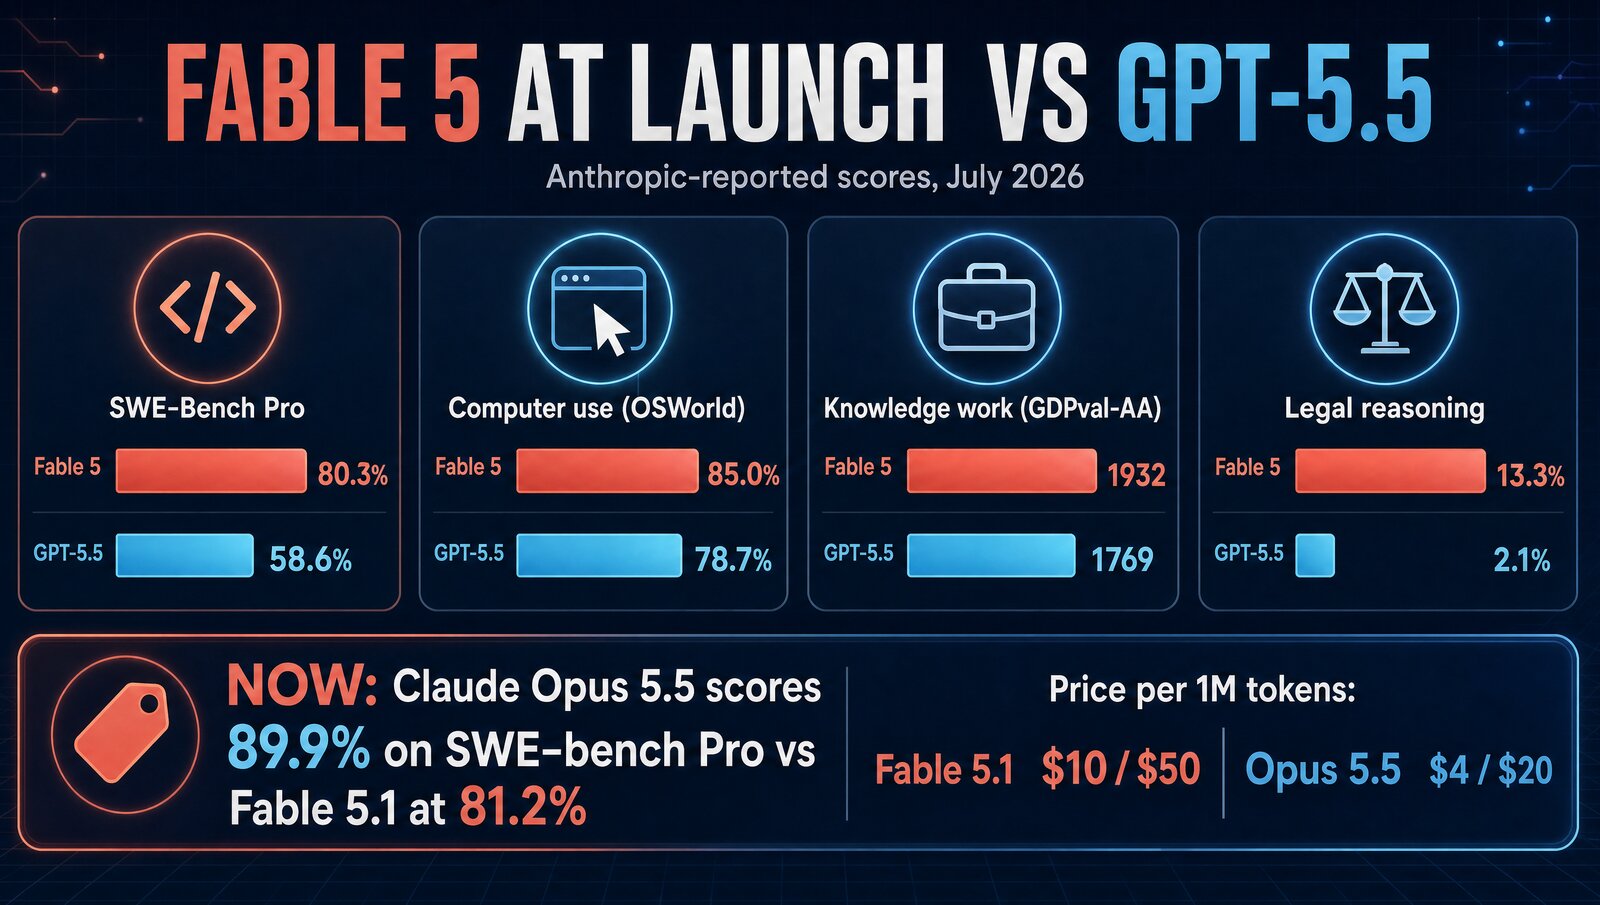
The biggest gap was on SWE-Bench Pro, the closest thing to "real GitHub issues, closed by AI": 22 points over GPT-5.5. Vendor benchmarks always deserve some skepticism, but the lead held across coding, computer use and knowledge work.
The 6 models at a glance
Claude Opus 5.5- 89.9% on SWE-bench Pro
- #1 on the Artificial Analysis index
- 1M context, no long-context surcharge
The catch: twice the price of Sonnet 5.5.
Claude Fable 5.1- Mythos-class, above Opus
- 81.2% on SWE-Bench Pro
- In Claude Pro (credits) and Max
The catch: 2.5 times Opus 5.5 for less on code.
Claude Sonnet 5.5- Launched September 28
- Close to Opus 5.5 on agentic and office work
- 1M context, no surcharge
The catch: escalate to Opus for the hardest jobs.
GPT-6 Astra- Built for science and computer automation
- Same list price as Fable 5.1
- Sol ($2/$10) and Luna ($0.10/$0.50) below it
The catch: $20/$75 past 272K tokens.
Gemini 4 Argon- Released October 13
- Rises to $4/$20 after the promo
- Promo price matches Sonnet 5.5
The catch: not on Free or Google AI Pro.
Grok 4.7- 500K context
- Grok 4.3 at $1.25/$2.50 with 1M
- Fewer content restrictions
The catch: price doubles past 200K tokens.
Cloud LLM API prices at a glance
Prices checked October 15, 2026, on each company's own pricing page.
| Model | Price per 1M tokens (in / out) | Context and limits | Best for |
|---|---|---|---|
| Claude Fable 5.1 | $10 / $50 | 1M | Brand voice, long-form drafting |
| Claude Opus 5.5 | $4 / $20 | 1M, no long-context surcharge | Best overall, hard agentic coding |
| Claude Sonnet 5.5 | $2 / $10 | 1M, no long-context surcharge | Everyday production work |
| Claude Haiku 5.5 | $0.10 / $0.50 (up to 100K-token prompts) | $0.50 / $2.50 past 100K | High-volume routine tasks |
| GPT-6 Astra | $10 / $50 | $20 / $75 past 272K | Science and computer automation |
| GPT-6 Sol | $2 / $10 | $4 / $15 past 272K | OpenAI's everyday default |
| GPT-6 Luna | $0.10 / $0.50 | $0.20 / $0.75 past 272K | Cheapest OpenAI model |
| Gemini 4 Argon | $2 / $10 through Nov 30, then $4 / $20 | Not on Free or Google AI Pro | Google's top model |
| Gemini 3.8 Flash | $0.75 / $3.75 through Dec 31 | Doubles to $1.50 / $7.50 in 2027 | Budget reasoning and agents |
| Grok 4.7 | $2 / $6 | 500K; doubles past 200K | xAI's flagship |
| Grok 4.3 | $1.25 / $2.50 | 1M; doubles past 200K | Cheap long context |
In July the field looked different: Opus 4.8 sat above Sonnet 5, GPT-5.4 cost $2.50/$15, and Grok 4.1 Fast was the cheapest option at $0.20/$0.50. Every one of those has since been replaced or undercut.
What each one offers
| Feature | Fable 5.1 | Opus 5.5 | Sonnet 5.5 | GPT-6 Astra | Gemini 4 Argon | Grok 4.7 |
|---|---|---|---|---|---|---|
| 1M-token context | ✓ | ✓ | ✓ | – | – | 500K |
| No long-context surcharge | – | ✓ | ✓ | ✗ | – | ✗ |
| Under $5 per 1M input tokens | ✗ | ✓ | ✓ | ✗ | ✓ | ✓ |
| In a $20 consumer plan | Credits | ✓ | ✓ | – | ✗ | – |
– means the company hasn't said.
Fable 5 vs GPT-5.4 and GPT-5.5
This was the head-to-head that mattered most for developers. Beyond the coding gap, Fable 5 hit 85.0% on OSWorld computer use, pushing past the 72.4% human expert baseline GPT-5.4 was first to beat. On legal reasoning the spread was 13.3% to 2.1%, small numbers but a clear direction.
GPT-5.4 still won on speed, cost per token and multimodal breadth like image generation and voice. For chat, quick snippets or content work, it was often the smarter buy.
Fable 5 vs Gemini 3 Ultra
Google didn't race on raw benchmarks. Google AI Ultra is a bundle: the models plus image and video generation, Flow credits, Chrome auto browse, the Jules coding agent, Project Genie, at least 20 TB of storage and YouTube Premium. It costs $99.99 a month for 5x AI Pro usage or $199.99 for 20x.
Gemini 3 Ultra was strong on multimodal work and useful inside Gmail, Drive and Calendar, but it didn't touch Fable 5 on hard agentic coding. Developers doing complex work wanted Fable; knowledge workers wanting one subscription for everything wanted Ultra. Since then Google has shipped Gemini 4 Argon as its top model.
Fable 5 vs Grok 4
xAI plays the opposite game: aggressive pricing, big context windows and less filtering. Grok 4.3 costs $1.25/$2.50 with 1M tokens of context, and Grok 4.7, the flagship since September, costs $2/$6. Both double in price past 200K tokens.
Grok also brings native video input. In July it sat well behind Fable 5 on the hard benchmarks, so for most developers it's the "can't justify Fable pricing" pick rather than the better model.
Where Fable fits in the Claude family now
Anthropic's lineup runs Haiku 5.5 for high-volume work, Sonnet 5.5 as the workhorse, Opus 5.5 for the hardest coding and research, and Fable 5.1 on top. Opus 5.5 now beats Fable 5.1 on SWE-bench Pro (89.9% vs 81.2%) at 40% of the price.
Run Sonnet 5.5 as your default and escalate to Opus 5.5 when it struggles. Running everything through Fable 5.1 is expensive and, since Opus 5.5 arrived, unnecessary.
Where Fable 5 shone, and where it's overkill
In July, three workloads justified the premium: multi-file agentic refactors, long-document analysis that needs real understanding, and autonomous multi-step web tasks. Opus 5.5 now covers most of them for less.
Casual chat, email, summaries, brainstorming and quick code snippets never needed it. Sonnet 5.5, GPT-6 Sol or even Haiku 5.5 handle those at a fraction of the cost.
What about the apps?
Fable was API-only at launch but is now in the Claude apps. Pro users can reach it with usage credits and Max plans include it within weekly limits. Both plans include Opus 5.5 and Sonnet 5.5, which is what most people should use.
Which one should you use?
The verdict
Fable 5 was the most capable cloud LLM of mid-2026, but Claude Opus 5.5 has taken that spot at a much lower price. Default to Sonnet 5.5, escalate to Opus 5.5, and keep Fable 5.1 for writing; see our Claude Opus 5.5 vs GPT-6 Astra ranking for the current picks.
FAQ
What is Claude Fable 5?
Claude Fable 5 is Anthropic's first widely available Mythos-class model, launched June 9, 2026, at $10 per million input tokens and $50 per million output, with a 1M context window. Anthropic reported 80.3% on SWE-Bench Pro. It has since been updated to Fable 5.1 (81.2% on SWE-Bench Pro, same price), and Claude Opus 5.5, released September 22, 2026, now matches or beats it on most tasks for $4/$20.
Is Fable 5 better than GPT-5.4 or GPT-5.5?
On agentic coding, yes. In July, Anthropic reported 80.3% on SWE-Bench Pro for Fable 5 versus 58.6% for GPT-5.5, and Fable 5 also led on computer use (85.0% vs 78.7%) and knowledge work (GDPval-AA 1932 vs 1769). All of those models have since been overtaken. Today the comparison that matters is Claude Opus 5.5 vs GPT-6 Astra, and Opus 5.5 leads it.
How much does Fable 5 cost?
Fable 5 and Fable 5.1 both cost $10 per million input tokens and $50 per million output tokens on the Claude API. That's 2.5 times Claude Opus 5.5 ($4/$20), five times Sonnet 5.5 ($2/$10) and the same list price as GPT-6 Astra. Most teams should now default to Sonnet 5.5 or Opus 5.5 and keep Fable for the jobs where it's clearly better.
What's a Mythos-class model?
It's the top tier Anthropic added above Opus in June 2026. Claude had three named sizes before: Opus (largest), Sonnet (mid) and Haiku (fastest). Fable 5 was the first publicly available Mythos-class model, and Mythos 5 exists too but skips the safety classifiers Fable includes, so it's more restricted in distribution. Fable is now on version 5.1.
Should I switch from GPT-5.4 to Fable 5?
Probably not to Fable 5. If you're still on GPT-5.4, test Claude Sonnet 5.5 or GPT-6 Sol first; both cost $2/$10 per million tokens. For the hardest agentic coding, test Claude Opus 5.5 at $4/$20. Fable 5.1 is mainly worth it now for brand voice and long-form drafting.