Our verdict: DeepSeek V4-Pro-0813 is the safest overall pick, with a plain MIT license and the cheapest official API here. GLM-5.3 and Kimi K3 are the coding and agent picks, and Qwen3.8 27B is the one you can run at home.
Four Chinese labs now give away models that trade blows with the best closed AI. DeepSeek, Z.ai (formerly Zhipu), Moonshot AI and Alibaba all shipped new open-weight releases between June and August 2026, and their own model cards put the top three within a point of each other on Terminal-Bench 2.1.

 DeepSeek V4-Pro
 GLM-5.3
 Kimi K3
 Qwen3.8 27B
Qwen 3.5
How big these models are
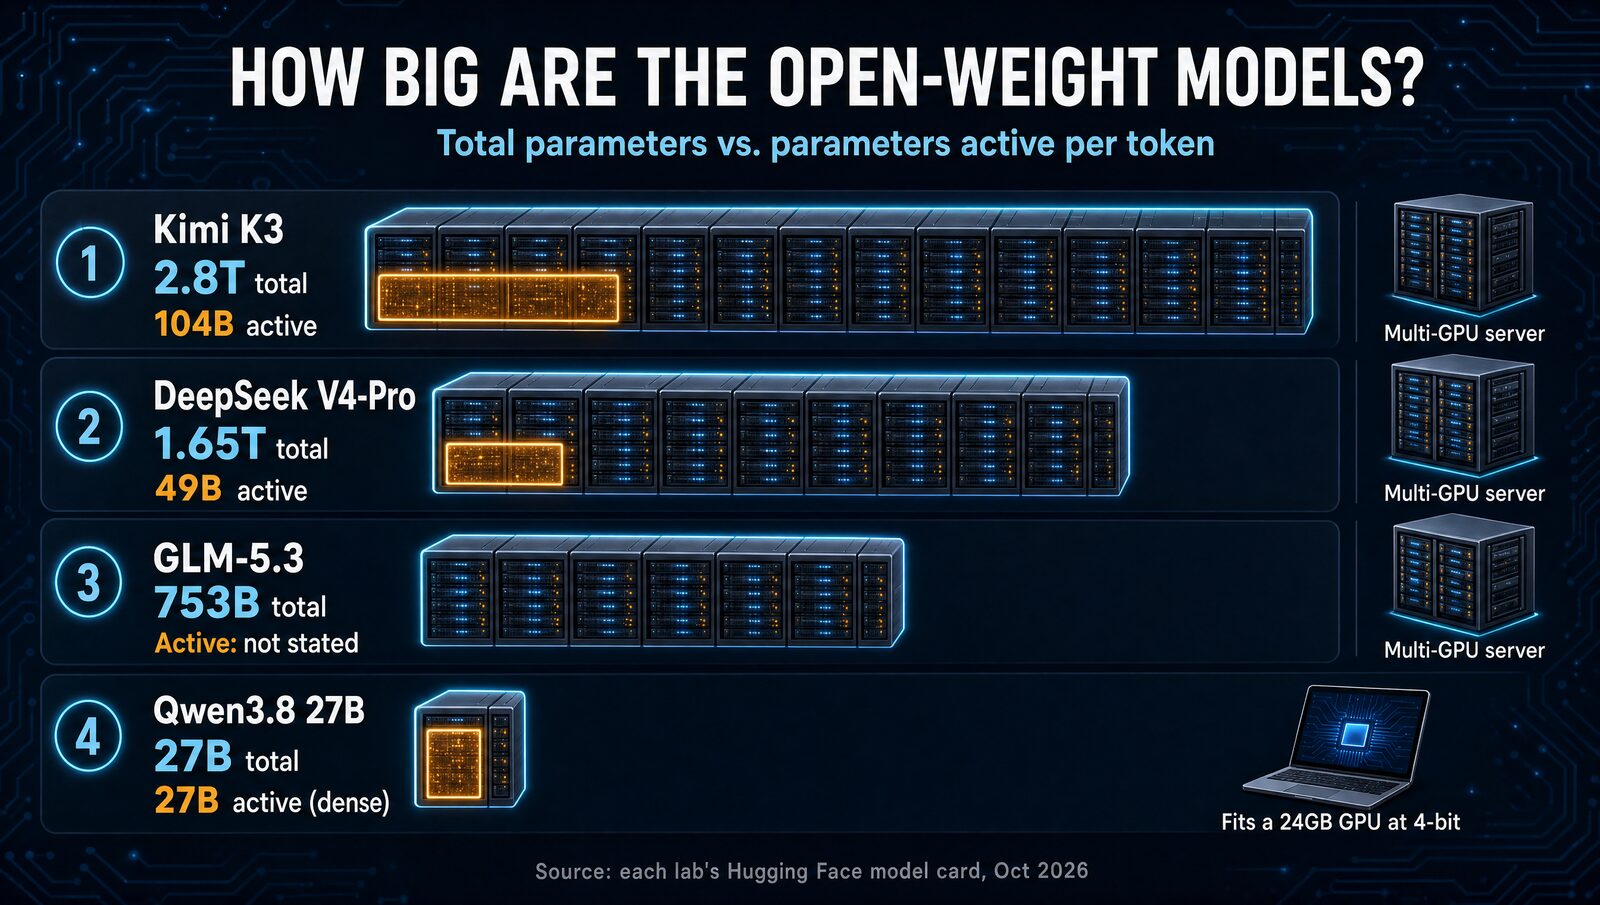
Total size decides how much memory you need. Active size decides speed, because a Mixture-of-Experts model only uses a slice of itself for each word. That's why a 2.8T model can answer quickly on a server, yet still won't fit on any desktop.
The 5 models at a glance
DeepSeek V4-Pro-0813- MIT license
- 1M token context
- API from $0.66/$1.98 per M tokens off-peak
The catch: text only, and server-sized.
GLM-5.3- 88.2 on Terminal-Bench 2.1
- 66.9 on DeepSWE
- MIT-style GLM-5.3 license
The catch: $10B+ API providers need a security review.
Kimi K3- Text, image and video input
- 1M token context
- 88.3 on Terminal-Bench 2.1
The catch: custom license, and the biggest here.
Qwen3.8 27B- Apache 2.0
- Reads images and video
- 262K context, extensible to 1M
The catch: a step below the giants on hard coding.
Qwen 3.5- Apache 2.0
- 201 languages and dialects
- Built-in vision encoder
The catch: older, and still big-workstation sized.
Specs and licenses
Specs checked October 23, 2026, on each lab's own Hugging Face model card. API prices are from DeepSeek's own pricing page.
| Model (newest) | Size (total / active) | License | Where it runs | Best for |
|---|---|---|---|---|
| DeepSeek V4-Pro-0813 | 1.65T / 49B | MIT | Multi-GPU server or DeepSeek API ($0.66/$1.98 per M tokens off-peak) | Overall capability at low API cost |
| GLM-5.3 | 753B | MIT-style, with a security review for very large API providers | Multi-GPU server | Agentic coding |
| Kimi K3 | 2.8T / 104B | Kimi K3 License (custom) | Multi-GPU server | Long agent sessions, multimodal |
| Qwen3.8 27B | 27B dense | Apache 2.0 | 24GB GPU at 4-bit, or a 32GB+ Mac | Running at home |
| Qwen 3.5 | 397B / 17B | Apache 2.0 | Big workstation or server | Multilingual (201 languages and dialects) |
What each one can do
| Feature | V4-Pro | GLM-5.3 | Kimi K3 | Qwen3.8 27B | Qwen 3.5 |
|---|---|---|---|---|---|
| Runs on a Mac | ✗ | ✗ | ✗ | ✓ | Mac Ultra |
| Commercial license | ✓ | $10B rule | With terms | ✓ | ✓ |
| Vision (image input) | ✗ | ✗ | ✓ | ✓ | ✓ |
| Coding (Terminal-Bench 2.1) | 87.9 | 88.2 | 88.3 | 73.0 | – |
– means the lab hasn't said. Scores are vendor-reported. Kimi K3's license asks API businesses over $20M a year to sign a separate deal. GLM-5.3-Flash, the smaller sibling, does take images.
DeepSeek V4-Pro: the overall leader
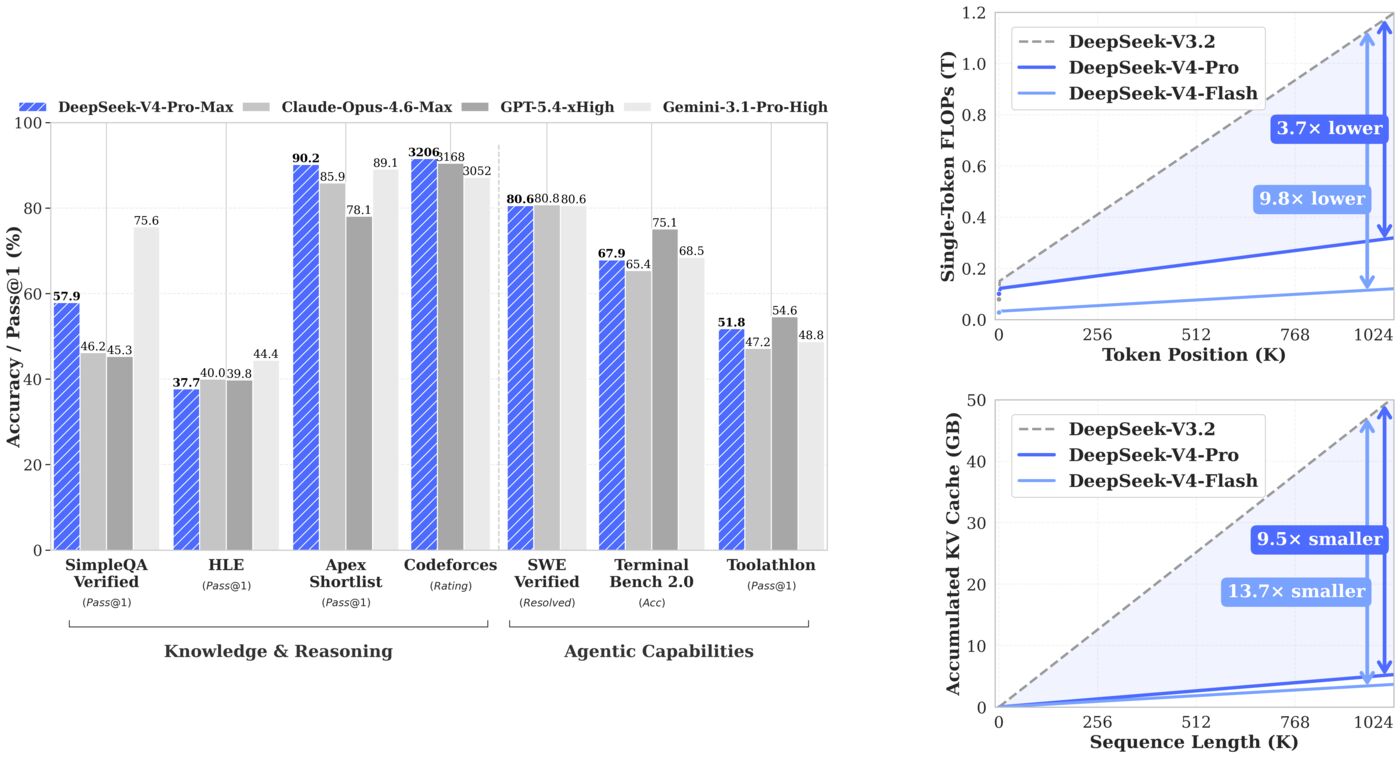
V4-Pro launched in April as a 1.6T Mixture-of-Experts model with 49B active, MIT-licensed, with a 1M token context. DeepSeek's card lists 80.6% on SWE-Bench Verified and 90.1% on GPQA Diamond for the Max variant. The August release, V4-Pro-0813, reports 87.9 on Terminal-Bench 2.1.
The API is the draw: $0.66 per million input tokens and $1.98 output off-peak, double that at peak. That's about 15x cheaper on input and 25x cheaper on output than Claude Fable 5.1 ($10/$50).
GLM-5.3: the coding specialist
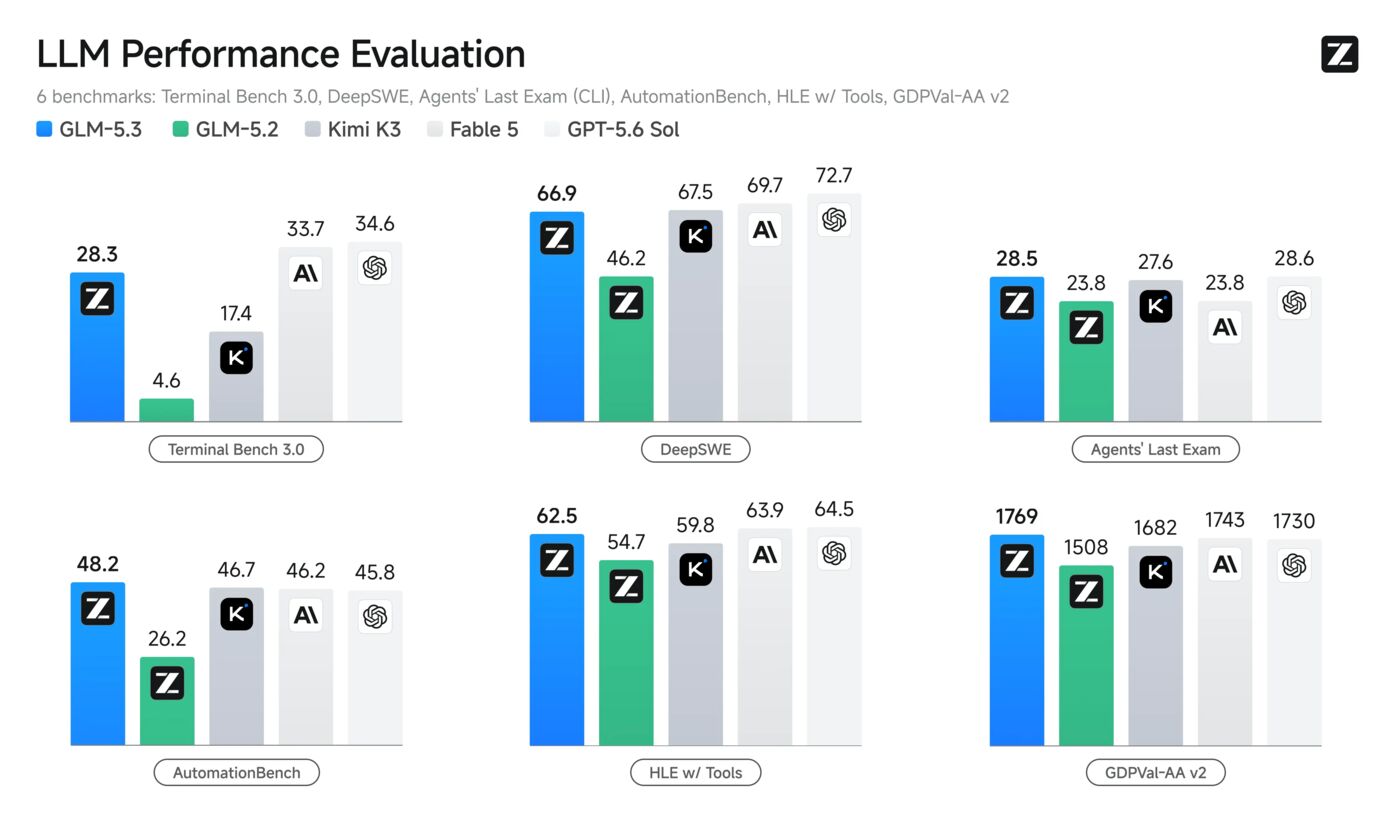
GLM-5.3 keeps GLM-5.2's 753B base and gets all its gains from post-training. Z.ai's card reports 88.2 on Terminal-Bench 2.1 and 66.9 on DeepSWE, and Z.ai calls it the most capable open-weight model for coding.
Its license is MIT-style with one condition: API providers earning over $10 billion a year must pass a Z.ai security review. GLM-5.3-Flash (320B, 18B active) is plain MIT.
Kimi K3: the long-session agent
Kimi K3 is the giant: 2.8T total with 104B active, a 1M token context, and native text, image and video input. Moonshot's card reports 88.3 on Terminal-Bench 2.1, and Moonshot pairs it with its Kimi Code CLI for long engineering sessions.
It ships under a custom Kimi K3 License rather than MIT. If you want a smaller Moonshot model with a Modified MIT license, Kimi K2.6 (1T, 32B active) is still available.
Qwen3.8 27B and Qwen 3.5: the practical picks
Qwen3.8 27B is the model most people can actually run. It's dense, Apache 2.0, reads images and video, and handles 262K tokens natively (extensible to 1M). It fits a 24GB GPU at 4-bit or a 32GB+ Mac.
Qwen 3.5 (397B, 17B active, Apache 2.0) remains the multilingual pick, with 201 languages and dialects. Apache 2.0 is also the license enterprise legal teams know best.
What hardware you need
| Memory | What runs |
|---|---|
| 16GB Mac | Strong 9B-to-12B low-bit models such as Gemma 4 12B |
| 24GB GPU or 32GB to 64GB Mac | Qwen3.8 27B, plus older 70B-class quantizations at 64GB |
| 128GB Mac | Step 3.5 Flash and 119B-to-122B models |
| 192GB Mac or multi-GPU | The original DeepSeek V4-Flash (roughly 160GB mixed FP4/FP8 checkpoint) |
| Multi-GPU server | V4-Pro, GLM-5.3, Kimi K3, V4.1-Flash, Qwen3.8 2.4T |
Full V4-Pro needs roughly 800GB of VRAM at full precision, about 10 H100 80GB GPUs. For every consumer tier from 16GB to 192GB, see our best local LLM by RAM guide.
Three ways to run them
| Path | Cost | Good for | You give up |
|---|---|---|---|
| Managed API (Together AI, Fireworks, DeepInfra, OpenRouter) | Pay per token | Most users, no setup | Privacy: the host sees your prompts |
| Rented GPUs (RunPod, Lambda, Vast.ai) | About $2 to $4.30 per H100 hour | Your own instance on demand | Setup time and cold starts |
| Own hardware (2-4 GPU workstation or Mac Studio Ultra) | $6,000 to $25,000 upfront | Daily use, full data control | Flexibility if architectures change |
For serving, use Ollama or LM Studio on a Mac or gaming PC, and vLLM or SGLang on a server. The DeepSeek, GLM and Kimi cards all include vLLM or SGLang launch recipes.
What about V4-Flash, V4.1-Flash and Kimi K2.6?
DeepSeek V4-Flash (284B, 13B active) is the original home-lab DeepSeek, workable at 192GB. V4.1-Flash is a different beast at 763B, MIT, 90.6 on Terminal-Bench 2.1, and DeepSeek's cheap API tier at $0.15/$0.60 off-peak. Kimi K2.6 was the first open model to beat GPT-5.4 on SWE-Bench Pro, at 58.6.
Which one should you use?
The verdict
DeepSeek V4-Pro-0813 is the best open-weight LLM for most teams in 2026: MIT-licensed, near the top on coding, and cheap on DeepSeek's own API. If you want one on your own machine, start with Qwen3.8 27B.
FAQ
Are Chinese open-source LLMs actually better than GPT-5.4?
On several benchmarks, yes. At release, GLM-5.1 scored 58.4 on SWE-Bench Pro versus GPT-5.4's 57.7 and Claude Opus 4.6's 57.3, and Kimi K2.6 scored 58.6, the first open-weight model to beat GPT-5.4 (xhigh) there. The newest releases push further: DeepSeek V4.1-Flash reports 90.6 on Terminal-Bench 2.1, Kimi K3 reports 88.3 and GLM-5.3 reports 88.2. These are vendor-reported scores, so treat them as a guide rather than a final ranking.
What hardware do I need to run GLM-5 or DeepSeek V4 locally?
It depends on size. The original DeepSeek V4-Flash (284B, 13B active) has an official mixed FP4/FP8 checkpoint of roughly 160GB before runtime and context, so 192GB of unified memory or a large multi-GPU setup is the practical starting point. The newer V4.1-Flash, DeepSeek V4-Pro, GLM-5.3 and Kimi K3 are much larger multi-GPU server models. Smaller dense models such as Qwen3.8 27B fit on a 24GB consumer GPU at 4-bit.
What's the best open-source LLM in 2026?
For overall capability, DeepSeek V4-Pro (now the 0813 release, MIT license, 1M context) is still the safest pick. For coding and agent work, GLM-5.3 and Kimi K3 are the newest contenders, both reporting about 88 on Terminal-Bench 2.1. For multilingual work, Qwen 3.5 (Apache 2.0, 201 languages and dialects). For a model you can run at home, Qwen3.8 27B (Apache 2.0). There's no single winner; the answer depends on your workload.
Can I actually run these models on a Mac?
Yes, but tier matters. A 16GB Apple Silicon Mac can run strong 9B-to-12B low-bit models. A 32GB to 64GB Mac runs Qwen3.8 27B comfortably and has room for older 70B-class quantizations. The original DeepSeek V4-Flash starts in roughly 192GB territory, while GLM-5.3, Kimi K3 and DeepSeek V4.1-Flash remain multi-GPU server models even at low precision.
How do I access these models if I can't run them locally?
Three paths. Managed APIs: DeepSeek's own API lists V4-Pro at $0.66 per million input tokens and $1.98 per million output tokens off-peak, and providers like Together AI, Fireworks, OpenRouter and DeepInfra host the major open models. Cloud GPU rental: RunPod and Lambda list H100s at roughly $2 to $4.30 an hour. Home cluster: a workstation with 2-4 GPUs or a Mac Studio Ultra gets you into large MoE territory. Managed APIs are the sanest starting point for most users.