Our verdict: Claude Opus 5.5 is the best AI model you can use right now. It's #1 on the leading independent intelligence index, leads the hardest public coding test and costs 40% of GPT-6 Astra's price. Claude Sonnet 5.5 is the best value, and Gemini 4 Argon ties Astra for a fraction of the price.
September was the most crowded month in AI this year. OpenAI shipped GPT-6 Astra on the 3rd, then Sol and Luna on the 22nd, the same day Anthropic released Claude Opus 5.5. Google answered with Gemini 4 Argon on October 13, and the rankings changed.
 Claude Opus 5.5
Claude Sonnet 5.5
 GPT-6 Astra
 Gemini 4 Argon
GPT-6 Sol
Claude Fable 5.1
Gemini 3.8 Flash
The intelligence leaderboard
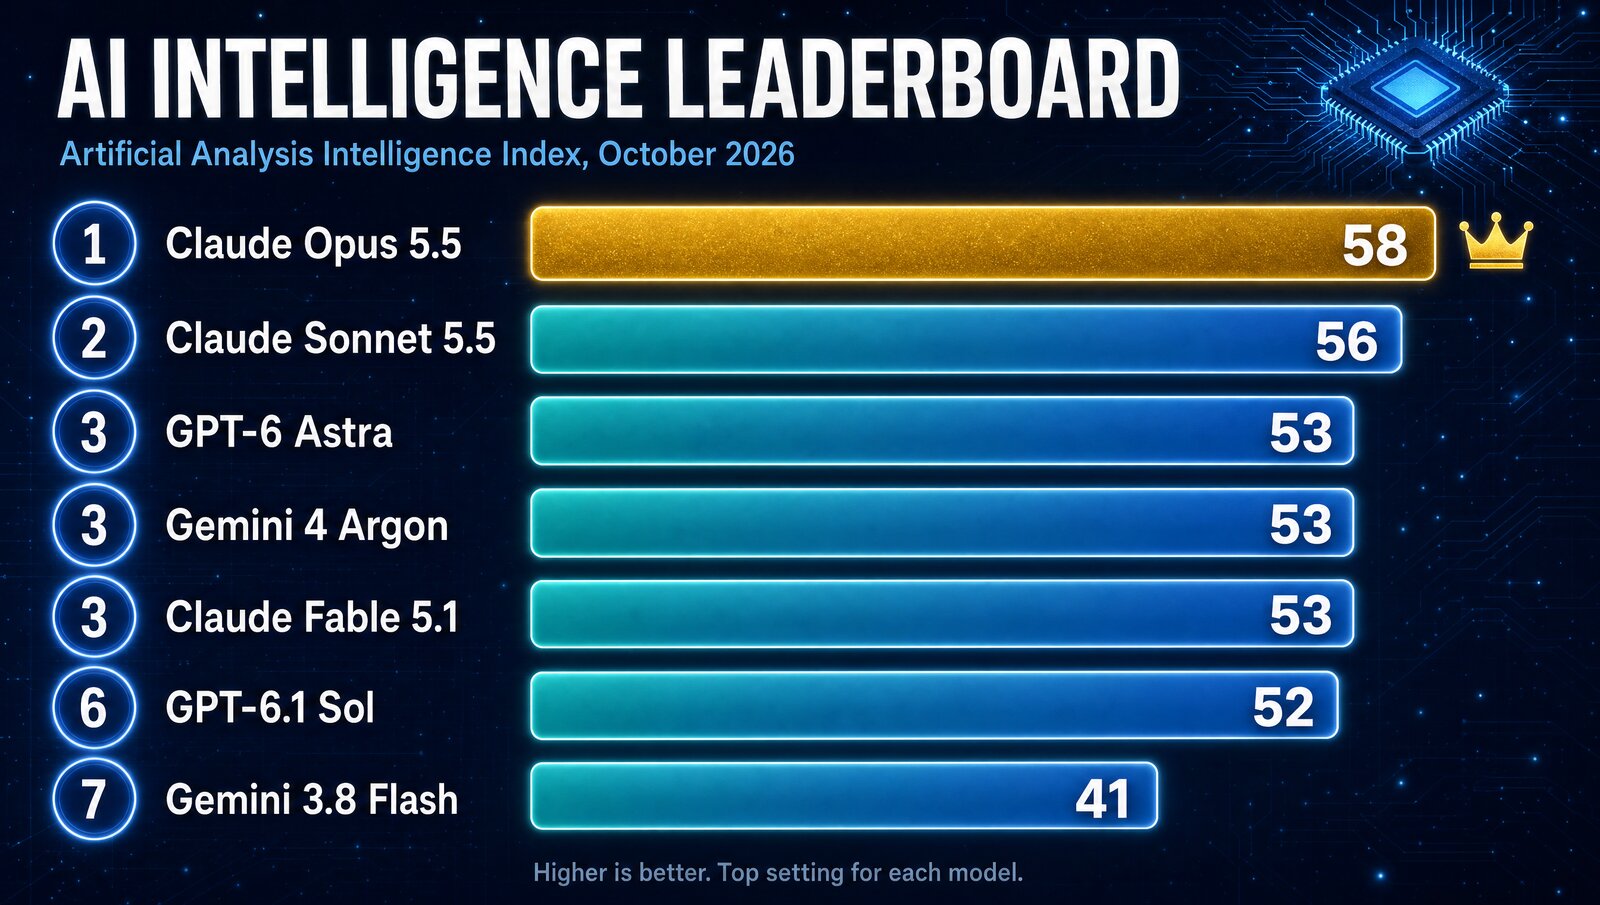
Labs publish benchmark tables that rarely overlap. Only seven tests appear in both Anthropic's and OpenAI's launch materials; Opus 5.5 leads four, Astra leads two, and one isn't comparable. So we weight the independent Artificial Analysis index most and treat vendor numbers as directional.
The 6 models at a glance
Claude Opus 5.5- Index score 58, #1
- 89.9% on SWE-bench Pro
- Best for agentic coding and hard engineering
The catch: max effort burns tokens.
Claude Sonnet 5.5- Index score 56, #2
- 70.6% on Terminal-Bench 4.0, ahead of Opus
- Best for everyday production work
The catch: trails Opus on the hardest jobs.
GPT-6 Astra- Index score 53
- Strong at science-heavy reasoning
- Best for computer-use automation
The catch: the most expensive option here.
Gemini 4 Argon- Index score 53, tied with Astra
- 1M tokens of input and output combined
- Best for Google Cloud and Workspace teams
The catch: the low price ends November 30.
GPT-6 Sol- Index score 52 (GPT-6.1 Sol)
- Roughly half GPT-5.6 prices
- Best for teams already on OpenAI
The catch: behind Sonnet 5.5 at the same price.
Claude Fable 5.1- Index score 53
- 81.2% on SWE-bench Pro
- Best for brand voice and long-form drafts
The catch: Opus 5.5 beats it for less.
The scoreboard
Prices checked October 15, 2026, on each company's own pricing page.
| Model | Released | Price per 1M tokens (in / out) | Context | AA Intelligence Index | SWE-bench Pro |
|---|---|---|---|---|---|
| Claude Opus 5.5 | Sep 22 | $4 / $20 | 1M, no surcharge | 58 (#1) | 89.9% |
| GPT-6 Astra | Sep 3 | $10 / $50 ($20 / $75 over 272K) | Surcharge past 272K | 53 | – |
| Gemini 4 Argon | Oct 13 | $2 / $10 (intro), $4 / $20 from Dec 1 | 1M input + output combined | 53 | – |
| Claude Fable 5.1 | Summer | $10 / $50 | – | 53 | 81.2% |
| Claude Sonnet 5.5 | Sep 28 | $2 / $10 | 1M, no surcharge | 56 | – |
| GPT-6 Sol / 6.1 Sol | Sep 22 | $2 / $10 | $4 / $15 past 272K | 52 (6.1 Sol) | – |
| Gemini 3.8 Flash | Sep 2 | $0.75 / $3.75 (through Dec 31) | – | 41 | – |
What each one can do
| Feature | Opus 5.5 | Sonnet 5.5 | Astra | Argon | Sol | Fable 5.1 |
|---|---|---|---|---|---|---|
| 1M-token context | ✓ | ✓ | – | ✓ | – | – |
| Vision (reads images and charts) | ✓ | ✓ | – | ✓ | – | ✓ |
| Cheapest tier ($2 / $10) | ✗ | ✓ | ✗ | To Nov 30 | ✓ | ✗ |
| Agent and computer use | ✓ | ✓ | ✓ | ✓ | – | ✓ |
– means the company hasn't said on its launch page.
What the price gap means in dollars
Take a busy internal coding assistant: 50 million input tokens and 10 million output tokens a month.
| Model | Monthly bill |
|---|---|
| Claude Sonnet 5.5 or GPT-6 Sol | $200 |
| Gemini 4 Argon | $200 through November 30, then $400 |
| Claude Opus 5.5 | $400 |
| GPT-6 Astra | $1,000, more if a request passes 272K tokens |
Astra has to be much better at your task to justify 2.5 times the bill. For most coding and knowledge work, it isn't.
Claude Opus 5.5: the new default
Opus 5.5 is built for long, multi-step work: agentic coding, research and tasks that run for hours. Its 89.9% on SWE-bench Pro is well ahead of Fable 5.1 (81.2%), and it holds a 1M-token window with no long-prompt penalty.
The catch: at maximum effort it thinks for a long time. Independent testers have seen a single hard agentic task cost around $13.
Claude Sonnet 5.5: Opus-level work for half the price
For most teams, Sonnet 5.5 (September 28) is the more important launch. It scores 56 on the index and beats Opus 5.5 on Terminal-Bench 4.0 (70.6% vs 66.4%). On the GDPval-AA office-work test it lands at 1,844 Elo, two points behind Opus and far ahead of GPT-6 Sol's 1,487.
Opus still leads FrontierCode (54.4% vs 52.1%). The practical setup: Sonnet as the default, Opus for problems Sonnet can't crack.
GPT-6 Astra: still the specialist
Astra aims at coding, research, computer use and multi-step professional work. It still leads on science-heavy reasoning and on automating software through a screen.
But at $10/$50, with the whole request repriced to $20/$75 once input passes 272,000 tokens, it's the costliest route to frontier quality. That surcharge rules it out for long documents.
Gemini 4 Argon: Google's comeback bid
Argon scores 53 on the index, level with Astra and five points behind Opus 5.5. Google says it ranks #1 on the Vals Index, but it hasn't published SWE-bench Pro scores that line up with the other labs' tables.
The price is the story. It's $2/$10 through November 30, then $4/$20. There's no free API tier; in the Gemini app it comes with Google AI Pro ($19.99 a month) and Ultra. See our Gemini 4 explainer.
GPT-6 Sol: OpenAI's everyday pick
Sol matters more to most OpenAI customers than Astra does. At $2/$10 it roughly halves GPT-5.6 costs, so if you're still on GPT-5.6, switch. GPT-6.1 Sol keeps the price, adds cheaper cached input and scores 52 on the index.
What about Fable 5.1 and Gemini 3.8 Flash?
Fable 5.1 is still a beautiful writer, worth keeping for brand voice and long-form drafting, but Opus 5.5 matches or beats it at 40% of the price. Gemini 3.8 Flash is Google's fast, cheap model, covered in our cheapest AI model verdict alongside Claude Haiku 5.5 and GPT-6 Luna at $0.10/$0.50.
Which model should you use?
Data that can't leave your servers? See our non-cloud LLM guide.
The verdict
Claude Opus 5.5 is the best AI model right now, with the top independent score, the top coding score and a price 60% below GPT-6 Astra's. Use Claude Sonnet 5.5 for everyday work, test Gemini 4 Argon while it's $2/$10, and pay for Astra only for science and automation.
FAQ
What is the best AI model in October 2026?
Claude Opus 5.5. Artificial Analysis ranks it #1 on its Intelligence Index with a score of 58, five points ahead of GPT-6 Astra, Claude Fable 5.1 and Google's new Gemini 4 Argon, and it leads SWE-bench Pro at 89.9%. GPT-6 Astra still wins some science and automation tasks.
How much does Claude Opus 5.5 cost?
$4 per million input tokens and $20 per million output tokens, with a 1M-token context window and no long-context surcharge. That's 40% of GPT-6 Astra's $10/$50 list price.
Is GPT-6 Astra worth the higher price?
For most teams, no. Astra costs $10/$50 per million tokens and $20/$75 once a request passes 272,000 input tokens. It's worth testing for science-heavy research and computer-use automation, but Opus 5.5 is cheaper and ahead on most shared benchmarks.
What happened to Claude Fable 5?
It was updated to Fable 5.1, which scores 81.2% on SWE-bench Pro and 53 on the Artificial Analysis index. Claude Opus 5.5 now matches or beats it on most tasks at a lower price, so most teams should default to Opus 5.5.
Is Claude Sonnet 5.5 better than Opus 5.5?
For most everyday work it's nearly as good for half the price. Sonnet 5.5, released September 28, 2026 at $2/$10 per million tokens, beats Opus 5.5 on Terminal-Bench 4.0 (70.6% vs 66.4%) and nearly ties it on office-work tests. Opus 5.5 still leads on the hardest coding and on the overall intelligence index.
What is GPT-6 Sol?
OpenAI's lower-cost GPT-6 model, released September 22 at $2 per million input tokens and $10 per million output tokens. A point update, GPT-6.1 Sol, is now on OpenAI's price list at the same rate with cheaper cached input. Independent tests place both behind Opus 5.5.
Where does Gemini 4 Argon rank?
Google released Gemini 4 Argon on October 13, 2026. It scores 53 on the Artificial Analysis Intelligence Index, tied with GPT-6 Astra and five points behind Claude Opus 5.5. It costs $2/$10 per million tokens through November 30, 2026, then $4/$20, the same as Opus 5.5.