Our verdict: Qwen3.8 27B is the best free local LLM you can run in 2026. It's a 27-billion-parameter model from Alibaba's Qwen team, released August 14 under the Apache 2.0 license, and it ranks #1 of 142 open models in its size class on the Artificial Analysis Intelligence Index. It still trails the cloud by a wide margin: 34 on the index, against 58 for Claude Opus 5.5.
You can now download an AI model for free, run it on one graphics card or a well-equipped Mac, and get answers that would have beaten the best paid chatbots of 2025. Nothing leaves your computer, there's no per-message bill, and it works with the Wi-Fi off.
 Qwen3.8 27B
Qwen3.6 35B-A3B
 gpt-oss
 Gemma 4
 DeepSeek V4.1 Flash
 GLM-5.3
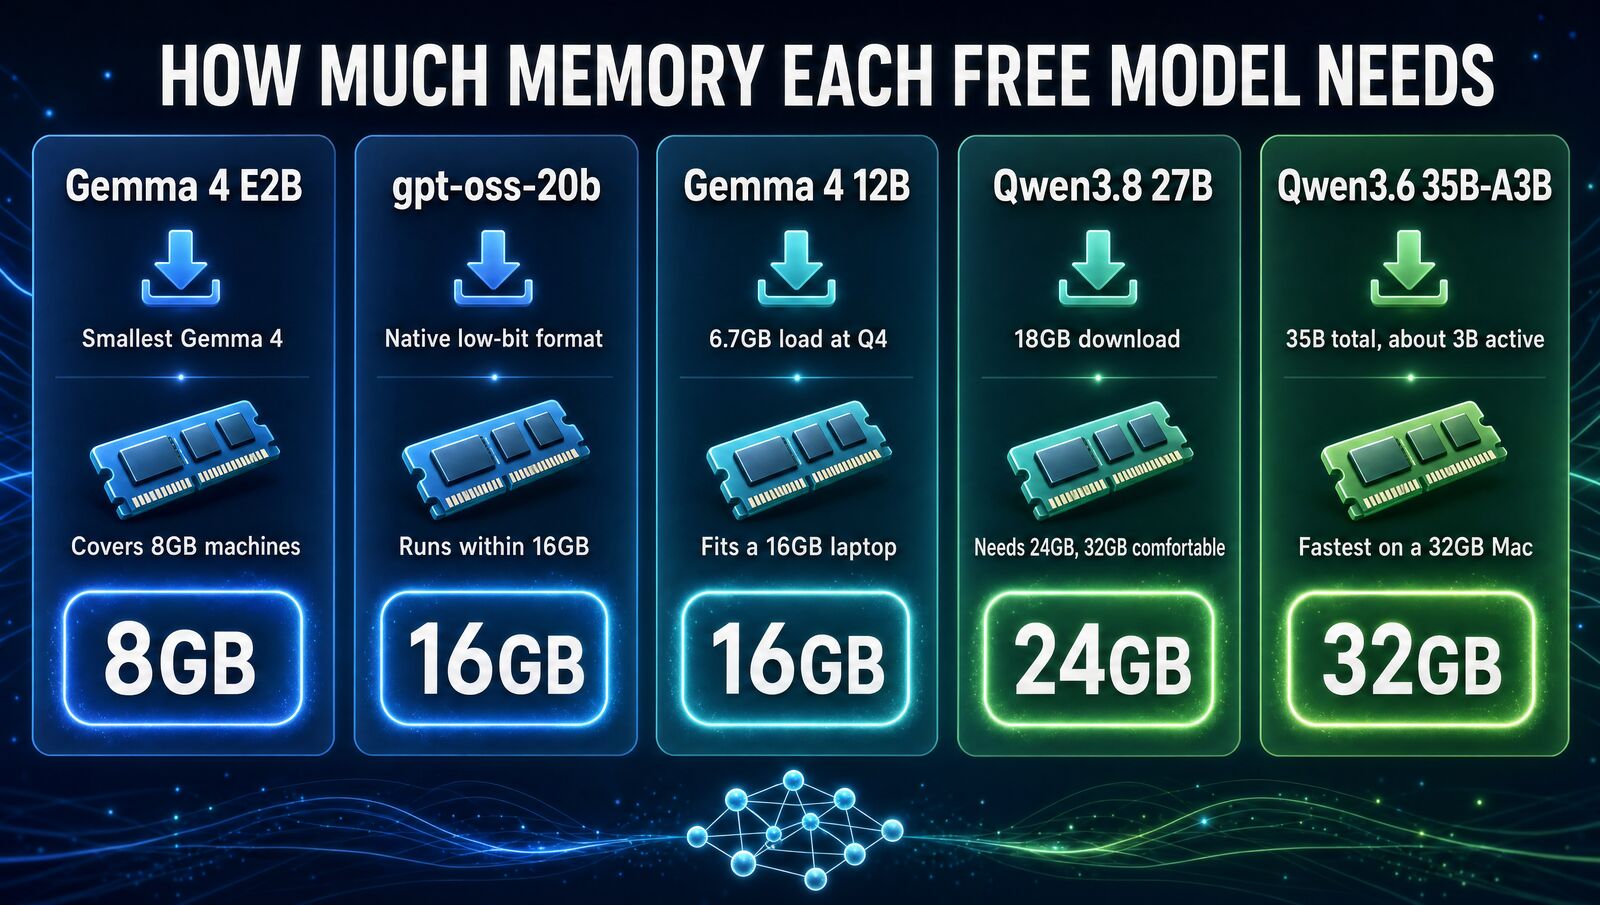
Memory decides which model you can run. Start from what your machine has, then pick the model.
The 4 local models at a glance
Qwen3.8 27B- #1 of 142 open models its size
- Reads images and video
- 262K-token context
The catch: needs 24GB, and 32GB to be comfortable.
Qwen3.6 35B-A3B- 35B total, a small slice used at a time
- Quickest in the 27B to 35B class
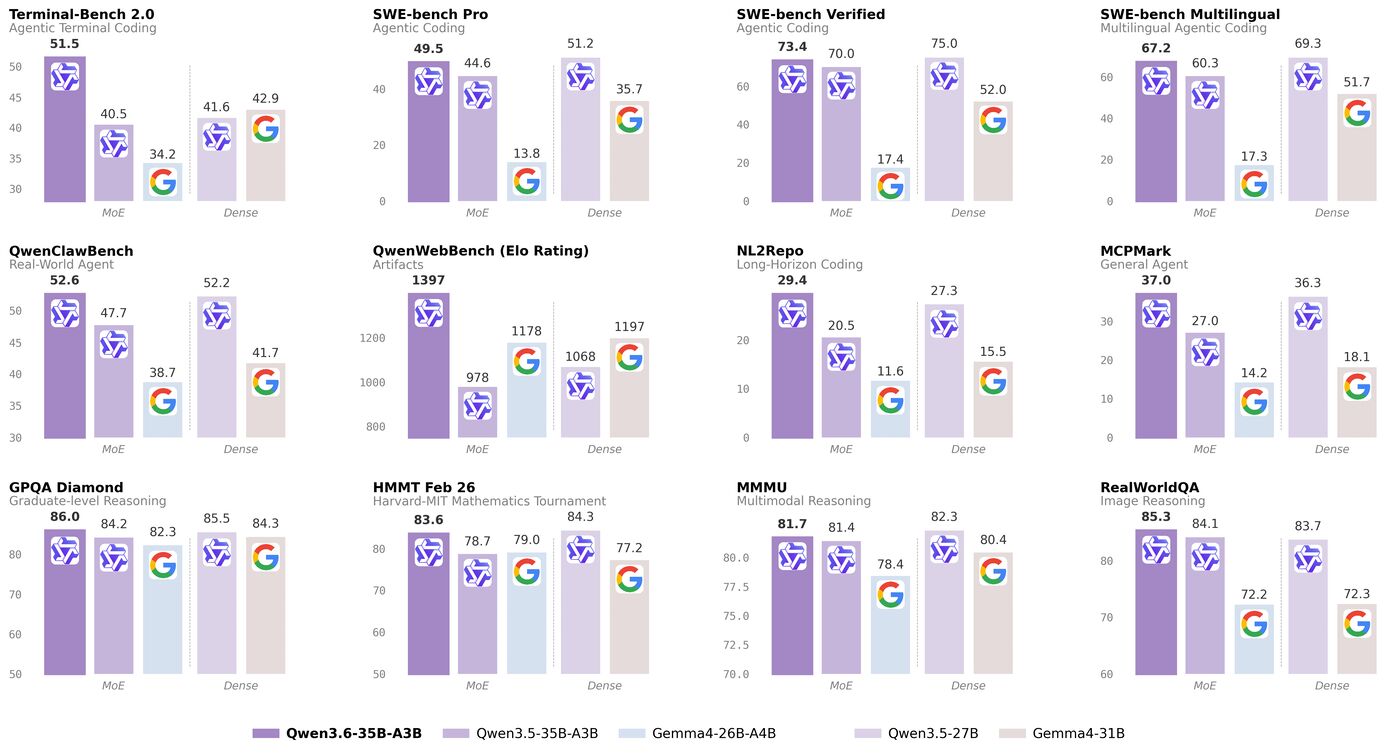
- Beats Gemma 4 26B-A4B on Qwen's charts
The catch: tight on a 24GB graphics card.
gpt-oss-20b- Runs within 16GB, OpenAI says
- Apache 2.0 license
- Fine for chat, summaries and simple code
The catch: text only, and weaker at reasoning.
Gemma 4- 12B loads in 6.7GB at Q4
- E2B covers 8GB machines
- 31B fits a 24GB GPU
The catch: the small sizes are noticeably weaker.
Local vs cloud: the scoreboard
The Artificial Analysis Intelligence Index rolls reasoning, coding, math and knowledge tests into one independent score. Prices checked October 23, 2026, on each company's own pricing page.
| Model | Type | AA Intelligence Index | Cost | Runs on |
|---|---|---|---|---|
| Claude Opus 5.5 | Cloud | 58 | $4 / $20 per 1M tokens | Anthropic's servers |
| GPT-6 Astra | Cloud | 53 | $10 / $50 per 1M tokens | OpenAI's servers |
| MiMo-V2.6-Pro | Open weights | 46 | Free to download | Multi-GPU server (300GB+) |
| GLM-5.3 | Open weights | 45 | Free to download | Multi-GPU server (300GB+) |
| Gemini 3.8 Flash | Cloud | 41 | $0.75 / $3.75 (promo through Dec 31) | Google's servers |
| DeepSeek V4.1 Flash | Open weights | 39 | Free, or $0.30 / $1.20 API | Multi-GPU server |
| Qwen3.8 27B | Open weights | 34 | Free | One 24GB GPU or a 32GB Mac |
The top open models, Xiaomi's MiMo-V2.6-Pro and Z.ai's GLM-5.3, come close to Gemini but need a rack of server GPUs. Qwen3.8 27B is the best model that fits hardware a person can actually buy. The median open model its size scores just 8.
What each one can do
| Feature | Qwen3.8 27B | Qwen3.6 35B-A3B | gpt-oss-20b | Gemma 4 12B |
|---|---|---|---|---|
| Free for commercial use | ✓ | – | ✓ | – |
| Reads images | ✓ | ✓ | ✗ | – |
| Fits a 16GB machine | ✗ | ✗ | ✓ | ✓ |
| Fits a 24GB GPU | ✓ | Tight | ✓ | ✓ |
| 256K+ context | ✓ | – | – | – |
– means we haven't confirmed it on the lab's own page. Tight means a smaller quantization or some CPU offload.
Qwen3.8 27B: best free local LLM
On Qwen's own tests it scores 61.7 on SWE-bench Pro and 89.2 on GPQA Diamond. Those are vendor numbers, so treat the independent index score of 34 as the one to trust.
It's a vision-language model, so it reads screenshots, charts and photos offline, and its 262K-token context holds a long codebase. One Ollama command pulls the default 4-bit build, an 18GB download, and Apache 2.0 allows commercial use.
What hardware you need
| Your machine | Best pick | What to expect |
|---|---|---|
| 8GB to 16GB laptop | gpt-oss-20b or the small Gemma 4 models | Fine for chat, summaries and simple code; noticeably weaker reasoning |
| 24GB Mac | Qwen3.8 27B (4-bit) | Works, but slow: under 10 tokens per second |
| 32GB Mac | Qwen3.6 35B-A3B for speed, Qwen3.8 27B for quality | Qwen3.8 runs about 5 to 6 tokens per second on a base M4 Mac mini |
| PC with a 24GB GPU (RTX 4090/5090) | Qwen3.8 27B | Fast: 40 to 57 tokens per second on typical replies |
| 96GB to 128GB workstation | gpt-oss-120b, larger quantized models | Near-cloud experience for most tasks |
For every memory tier from 8GB to 192GB, see Best Local LLM by RAM or try our RAM calculator.
Qwen3.6 35B-A3B: the speed pick
It holds 35 billion parameters but uses only about 3 billion for each word, so it answers faster than Qwen3.8 on a 32GB Mac. All 35B still have to sit in memory, which makes a 24GB graphics card tight.
gpt-oss-20b: best for a 16GB laptop
OpenAI says gpt-oss-20b runs within 16GB in its native low-bit format, and it's Apache 2.0 like Qwen. It handles chat, summaries and simple code, but it's text only and noticeably weaker at hard reasoning than Qwen3.8 27B.
Its big sibling, gpt-oss-120b, targets a single 80GB GPU, so plan on a 96GB or bigger machine.
Gemma 4: the small-machine family
Google lists a 6.7GB Q4 load for Gemma 4 12B, so it fits a 16GB laptop with room to spare, and E2B covers 8GB machines. At the top, the 31B loads in 17.5GB and fits a 24GB GPU.
Local vs cloud: where each wins
Local wins on privacy, cost and control. Client documents, medical notes and code under an NDA never leave your machine, and there's no subscription, per-token bill or rate limit.
The cloud wins on hard problems. Long coding tasks and tricky reasoning still belong to Claude Opus 5.5 or GPT-6, which are 20-plus points ahead on the index and much faster than a laptop. The smart setup uses both. If you'd rather pay a little than buy hardware, GPT-6 Luna costs $0.10 per million input tokens.
How to run it
Ollama suits developers: one command, ollama run qwen3.8, downloads and runs the model with a local API. LM Studio suits tinkerers who want to compare builds and tune settings. Jan suits newcomers with a ChatGPT-style window that runs offline. We compare them in Ollama vs LM Studio.
What about the server-sized open models?
MiMo-V2.6-Pro, GLM-5.3 and DeepSeek V4.1 Flash score 39 to 46 on the index, well above Qwen3.8, but they need multi-GPU servers. DeepSeek V4.1 Flash is the easy way to try one: $0.30 per million input tokens on DeepSeek's own API. The full field is in Best Non-Cloud LLMs 2026.
Which one should you use?

The verdict
Qwen3.8 27B is the best free local LLM of 2026. It's the smartest model that fits a single graphics card or a 32GB Mac and it's free for any use, though Claude Opus 5.5 and GPT-6 still win on the hardest problems.
FAQ
What is the best free local LLM in 2026?
Qwen3.8 27B, released August 14, 2026 under the Apache 2.0 license. It ranks first of 142 open-weight models in its size class on the Artificial Analysis Intelligence Index with a score of 34, and runs on a 24GB graphics card or a Mac with 32GB of memory.
How does a local LLM compare to ChatGPT and Claude?
The best local model scores 34 on the Artificial Analysis Intelligence Index, against 58 for Claude Opus 5.5 and 53 for GPT-6 Astra. It's good enough for everyday writing, summaries and simple coding, but frontier cloud models are still clearly better at hard reasoning and long coding tasks.
How much RAM do I need to run a local LLM?
16GB runs smaller models like gpt-oss-20b. About 24GB is the practical minimum for Qwen3.8 27B, and 32GB is comfortable. A PC with a 24GB graphics card runs it fastest. The largest open models need 128GB or more.
Is Qwen3.8 safe and free for commercial use?
It's released under the Apache 2.0 license, which allows free commercial use. When run locally, your prompts and files stay on your computer. As with any model, review outputs before relying on them for important work.
What is the best local LLM for a 16GB laptop?
gpt-oss-20b or one of the smaller Gemma 4 models. They handle chat, summaries and light coding well, but they're noticeably weaker at complex reasoning than Qwen3.8 27B.