 Claude Fable 5.2
The top score on FrontierCode 2.0 and on the independent Intelligence Index, at the same $8/$40 price as GPT-6.2 Astra and nearly twice the speed.
Claude Opus 5.5$4 / $20 GPT-6.2 Sol$1.01
 Claude Pro$20 a month
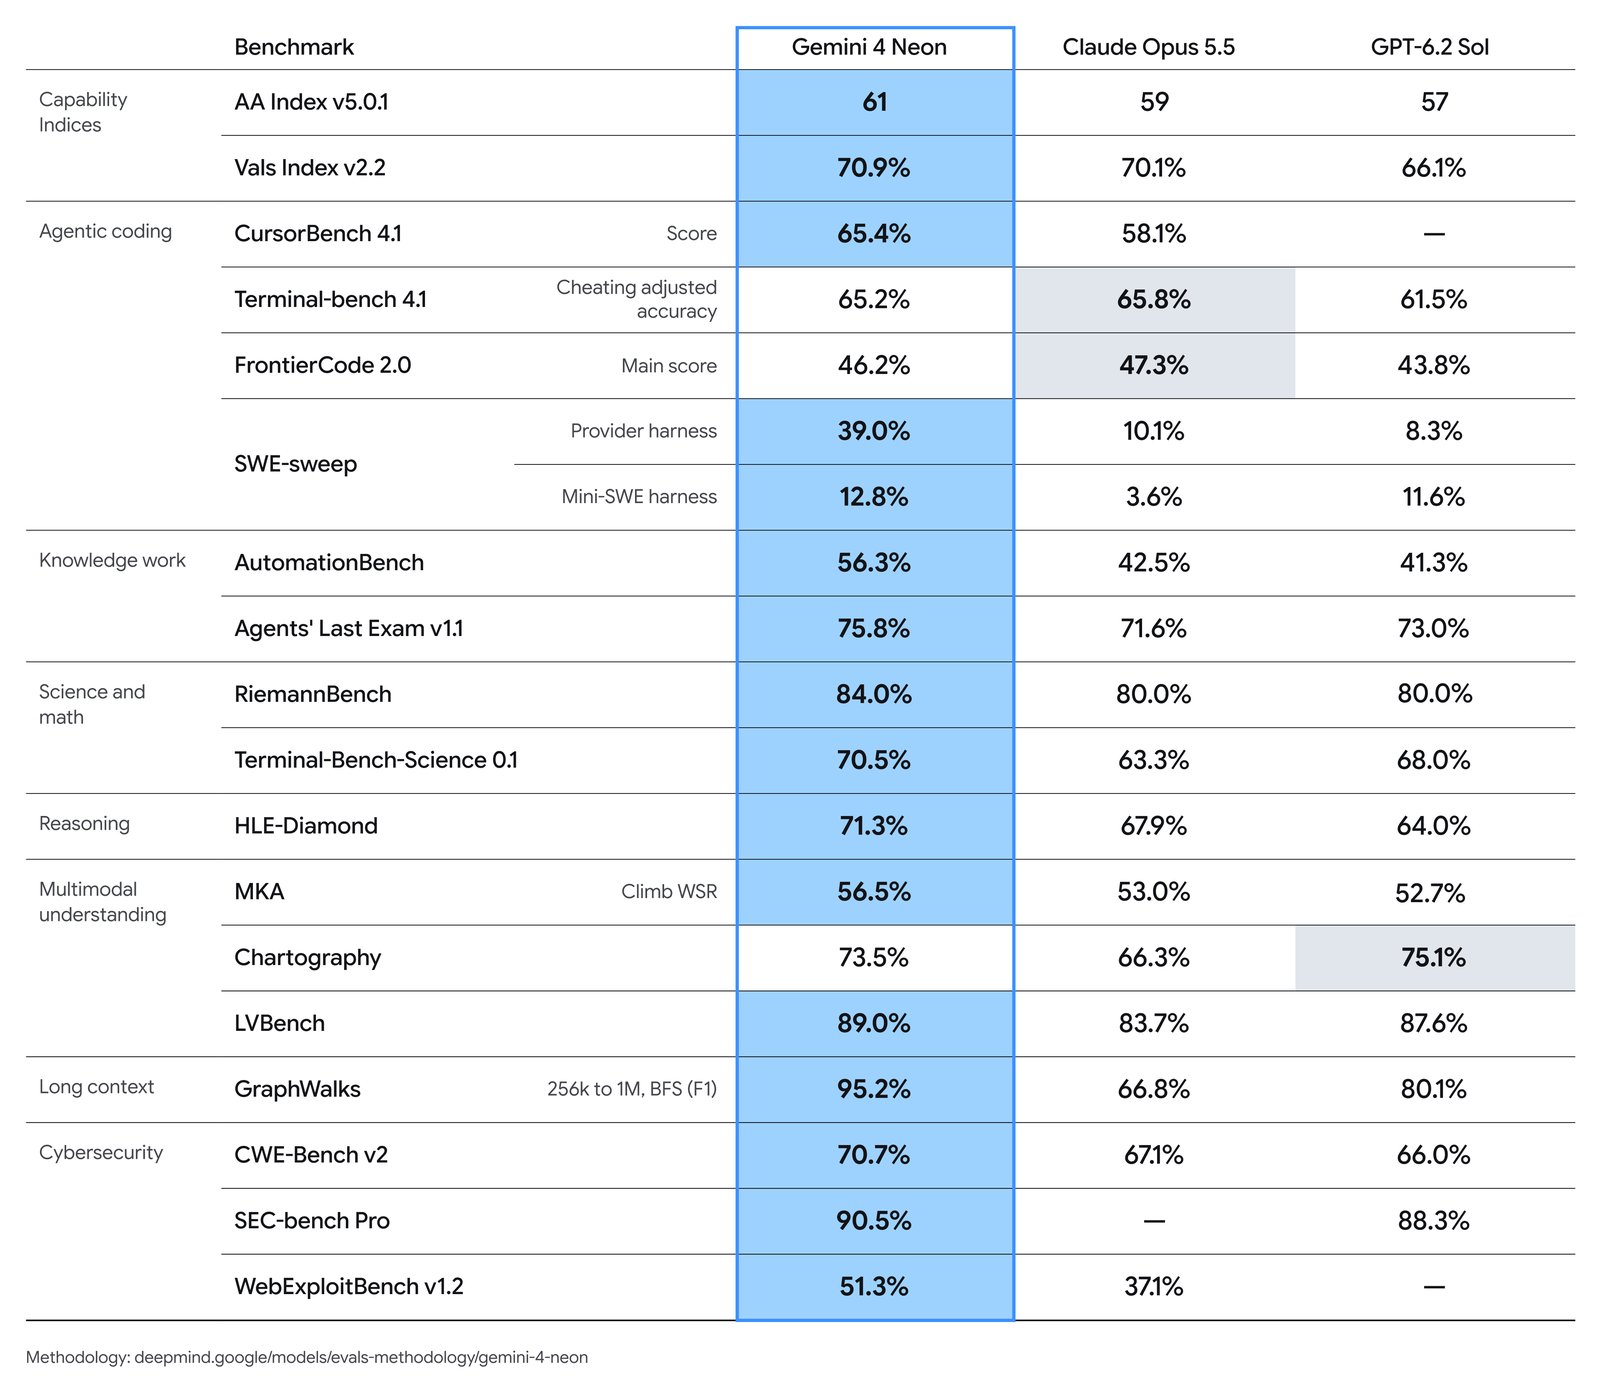
Claude Fable 5.2 is the best AI for coding in November 2026. It scores 49.1% on FrontierCode 2.0, the highest published result, and it leads the independent Intelligence Index at 65. For most developers the smarter buy is Claude Opus 5.5, which comes within two points of Fable on that test for half the price and sits inside the $20 Claude Pro plan.
This guide covers the five models that matter today, Claude Fable 5.2, Claude Opus 5.5, GPT-6.2 Astra, GPT-6.2 Sol and Gemini 4 Neon, and the five tools you run them in. For general chat, writing and research, see our best AI model guide, where we ran all of them through hands-on tests.
Which AI should you code with?
Pick the kind of work you do and your budget. We'll match you with a plan or model, what it costs and a runner-up.
Coding benchmarks, side by side
FrontierCode 2.0 tests merge-ready changes to real codebases, Terminal-Bench 4.1 tests agents working in a terminal, FrontierSWE v2 tests real software-engineering tasks and CursorBench 4.1 tests coding inside the Cursor editor. A dash means the vendor didn't publish that result.
| Test | Fable 5.2 | Opus 5.5 | Astra | Sol | Neon |
|---|---|---|---|---|---|
| FrontierCode 2.0Real codebases | 49.1% | 47.3% | 44.2% | 43.8% | 46.2% |
| Terminal-Bench 4.1Terminal agents | – | 65.8% | – | 61.5% | 65.2% |
| FrontierSWE v2Software engineering | 69.9% | 62.3% | 65.5%* | – | – |
| CursorBench 4.1Coding in Cursor | – | 58.1% | – | – | 65.4% |
| Intelligence IndexIndependent, all tasks | 65 | 59 | 62 | 57 | 61 |
Fable 5.2 FrontierCode and FrontierSWE, plus Astra's FrontierSWE: Anthropic (*the original GPT-6 Astra, not 6.2). Opus 5.5, Sol and Neon FrontierCode, Terminal-Bench and CursorBench: Google DeepMind. Astra FrontierCode: iClarified, reporting OpenAI's launch figures. Intelligence Index: Artificial Analysis. Vendors ran these tests themselves, on different settings, so treat gaps of a point or two as ties. Anthropic reports 45.5% for Opus 5.5 on FrontierCode under its own settings. Checked November 18, 2026.
Fable 5.2 wins every test it was scored on. The rest sit within about five points of each other, which is why price and speed matter more than the last point of accuracy. We found no published SWE-bench Verified or SWE-bench Pro scores from any vendor for these models; the labs have moved to FrontierCode, FrontierSWE and Terminal-Bench.
What a coding task costs
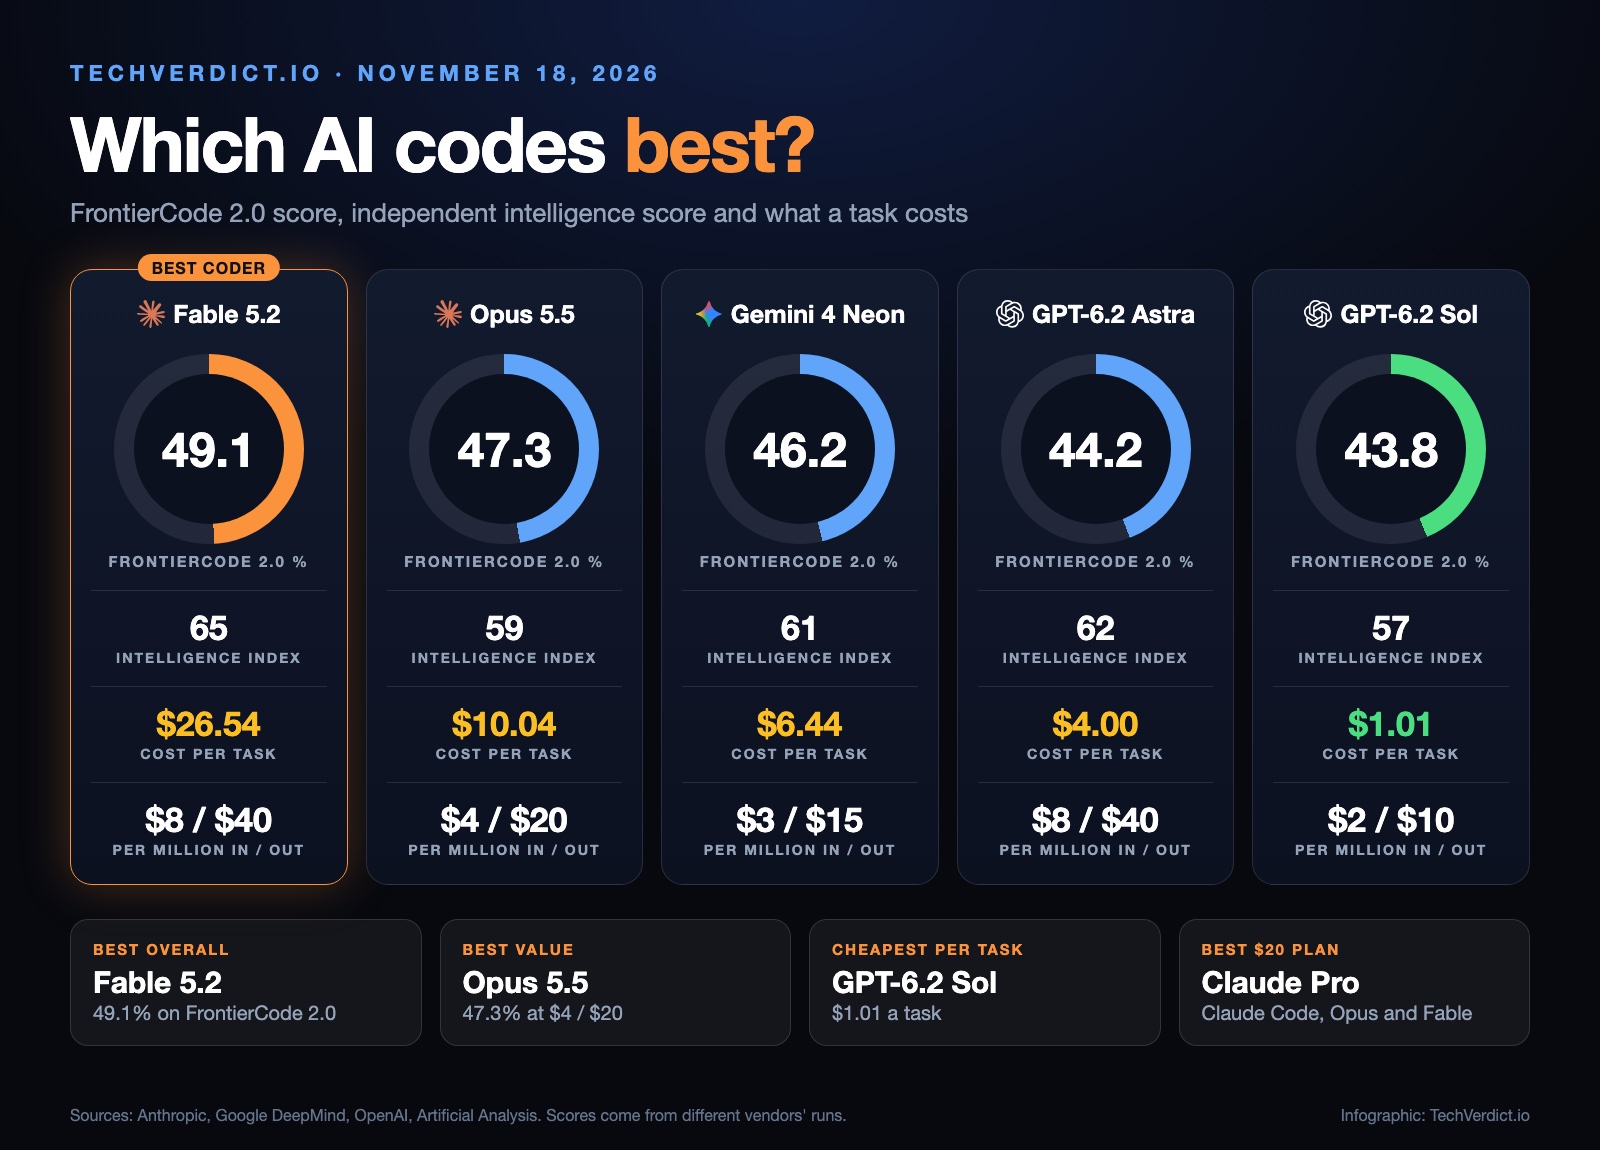
Price per token misleads, because wordy models burn more tokens. Cost per task is what Artificial Analysis actually spent to run one task from its test suite, so it counts the chatter too.
| Model | Per million in / out | Cost per task | Speed (tokens/s) |
|---|---|---|---|
| Claude Fable 5.2 | $8 / $40 | $26.54 | 112 |
| Claude Opus 5.5 | $4 / $20 | $10.04 | 117 |
| Gemini 4 Neon | $3 / $15 | $6.44 | 110 |
| GPT-6.2 Astra | $8 / $40 | $4.00 | 66 |
| GPT-6.2 Sol | $2 / $10 | $1.01 | 85 |
Prices from Anthropic, OpenAI and Google. Cost per task and speed from Artificial Analysis, each model at its top setting, across all its test tasks rather than coding alone. Astra and Sol bill more above 272,000 input tokens. Checked November 18, 2026.
Sol is the bargain: about a dollar a task and within half a point of Astra on FrontierCode 2.0, according to OpenAI. Fable costs 26 times as much per task as Sol for a five-point lead on that test, which pays off only when a failed attempt costs you hours.
Which coding tool should you use?
The model is half the choice. The other half is the tool that lets it read your project, run your tests and edit files. Our repo-aware AI comparison goes deep on how each one sees your code; here is the price and model picture for November.
| Tool | Cheapest paid plan | Free plan | Heavy use |
|---|---|---|---|
| Claude Code | Claude Pro, $20 | No | Max, $100 or $200 |
| Codex | ChatGPT Plus, $20 | Limited | Pro, $100, $200 or $500 |
| Cursor | Premium, $30 (Plus, $8) | Yes | Super $100, Ultra $200 |
| Antigravity | Google AI Pro, $19.99 | Yes | Ultra, $99.99 or $199.99 |
| GitHub Copilot | Pro, $10 | Yes | Pro+ $39, Max $100 |
Prices from Anthropic, OpenAI, Cursor, Google Antigravity and GitHub, with Google AI Pro and Ultra prices as in our best AI subscription guide. Checked November 18, 2026.
| Feature | Claude Code | Codex | Cursor | Antigravity | Copilot |
|---|---|---|---|---|---|
| Terminal agent | ✓ | ✓ | – | ✓ | – |
| Works inside an editor | ✓ | ✓ | ✓ | ✓ | ✓ |
| Free plan | ✗ | Limited | Limited | ✓ | Limited |
| Claude Fable 5.2 / Opus 5.5 | ✓ | ✗ | Billed extra | Paid plans | – |
| GPT-6.2 Astra / Sol | ✗ | ✓ | Billed extra | ✗ | – |
| Gemini 4 Neon | ✗ | ✗ | – | Paid plans | – |
A dash means the company hasn't said. Fable 5.2 isn't listed for Antigravity; Opus 5.5 is. Cursor bills third-party models at API list price from prepaid credit on Premium and above. Terminal and editor support are from each vendor's product pages and our repo-aware AI comparison.
Using Claude Code every day? Our guides to the best Claude Code MCP servers, the best laptop for Claude Code and the best monitor for coding with AI cover the setup, and Claude Chat vs Code vs Cowork explains where Claude Code fits in the plan.
Each model, in one card
Claude Fable 5.2- Think of it as the senior specialist you call in when everyone else is stuck
- 49.1% on FrontierCode 2.0 and 69.9% on FrontierSWE v2
- Fast mode runs up to 2.5x faster for $16 / $80
The catch: $26.54 a task, the priciest here.
Claude Opus 5.5- Think of it as the experienced colleague who does the daily work at half Fable's rate
- Top Terminal-Bench 4.1 score in Google's table, 65.8%
- Fastest here at 117 tokens a second, and in Claude Pro
The catch: it gave a muddled break-even note in one of our tests.
GPT-6.2 Astra- Think of it as a sharp hire who sometimes clocks out early
- Reviewers praise its code reviews
- In Codex on ChatGPT Plus, $20 a month
The catch: slowest here at 66 tokens a second, and early testers report it stopping long jobs.
GPT-6.2 Sol- Think of it as Astra's little cousin, who works just as hard for a lot less
- 43.8% on FrontierCode 2.0, about $1.01 a task
- Also in Codex on ChatGPT Plus
The catch: 61.5% on Terminal-Bench 4.1, behind Opus 5.5 and Neon.
 Gemini 4 Neon
- Think of it as Google's new hire: nearly as good as the seniors, but it talks a lot
- Leads CursorBench 4.1 at 65.4%
- In Antigravity on Google AI Pro, $19.99
The catch: its tasks took 21.5 minutes against a 12.4-minute median for similar models. We haven't tested its coding ourselves yet.
Neon's numbers come from Google and Artificial Analysis, and we have not run it. Our Gemini 4 Neon vs Opus 5.5 vs Sol comparison covers its non-coding strengths.
What about…
The verdict
Use Claude Fable 5.2 when the job is hard, Claude Opus 5.5 for everything else. Both come with Claude Code in a $20 Claude Pro plan, which makes it the best $20 coding plan today. Pick GPT-6.2 Sol through Codex if cost per task matters most, Gemini 4 Neon if you live in Cursor or Antigravity, and GitHub Copilot Pro at $10 if you mostly want completions.
FAQ
What is the best AI for coding?
Claude Fable 5.2 is the best AI for coding right now, with 49.1% on FrontierCode 2.0 and the top Intelligence Index score at 65. Claude Opus 5.5 is the better buy for most people, at 47.3% on FrontierCode 2.0 and half the price of Fable.
Is Claude better than ChatGPT for coding?
On today's published numbers, yes. Fable 5.2 scores 49.1% on FrontierCode 2.0 and Opus 5.5 scores 47.3%, against 44.2% for GPT-6.2 Astra and 43.8% for GPT-6.2 Sol. Early testers also report Astra stopping long jobs, though reviewers like its code reviews.
Is Gemini 4 Neon good for coding?
Yes, on Google's numbers. Neon scores 46.2% on FrontierCode 2.0, 65.2% on Terminal-Bench 4.1 and 65.4% on CursorBench 4.1, ahead of Opus 5.5 on that last test. It's slow and wordy at its top setting, and we haven't tested it ourselves.
What is the cheapest AI for coding?
GPT-6.2 Sol is the cheapest strong coder: $2 per million input tokens, $10 per million output, and about $1.01 a task on Artificial Analysis. For a subscription, GitHub Copilot Pro is $10 a month and Cursor Plus is $8.
What is the best free AI for coding?
Antigravity's free plan is the best free coding agent, with a weekly quota and no Gemini 4 models. For chat help, Claude Free and ChatGPT Free work well, and GitHub Copilot Free gives 2,000 completions a month.
Is GPT-6.2 Astra good for coding?
It's good for short tasks and code reviews, and shaky on long ones. It scores 44.2% on FrontierCode 2.0, and early testers including Theo Browne report it stalling on multi-day jobs. Sol costs a quarter as much and scores 43.8%.
Claude Code vs Codex vs Cursor: which should I use?
Use Claude Code if you want the strongest models for $20 a month. Use Codex if you already pay for ChatGPT, and Cursor if you want the most polished editor. Our repo-aware AI comparison covers how each one reads your project.
Is GitHub Copilot still worth it?
Yes, as the cheapest paid option. Copilot Pro is $10 a month with 1,500 AI credits and an agent, and Pro+ is $39. For long agent sessions on the newest models, Claude Code or Codex gives you more for $20.