Our verdict: Firecrawl is the best web scraping API for AI in 2026. Choose Apify when you need a ready-made scraper for a specific site, Bright Data when the target fights back hard, and Crawl4AI if you want it free on your own machine.
Every AI agent, RAG pipeline and research bot eventually needs the live web. Raw HTML is full of menus, scripts and cookie banners that waste tokens, and many sites block anything that looks like a bot. A web scraping API for AI renders the page, gets past the blocks and hands your model clean markdown or JSON.
 Firecrawl
Apify
Bright Data
Crawl4AI
 Jina Reader
 Exa
The numbers that matter
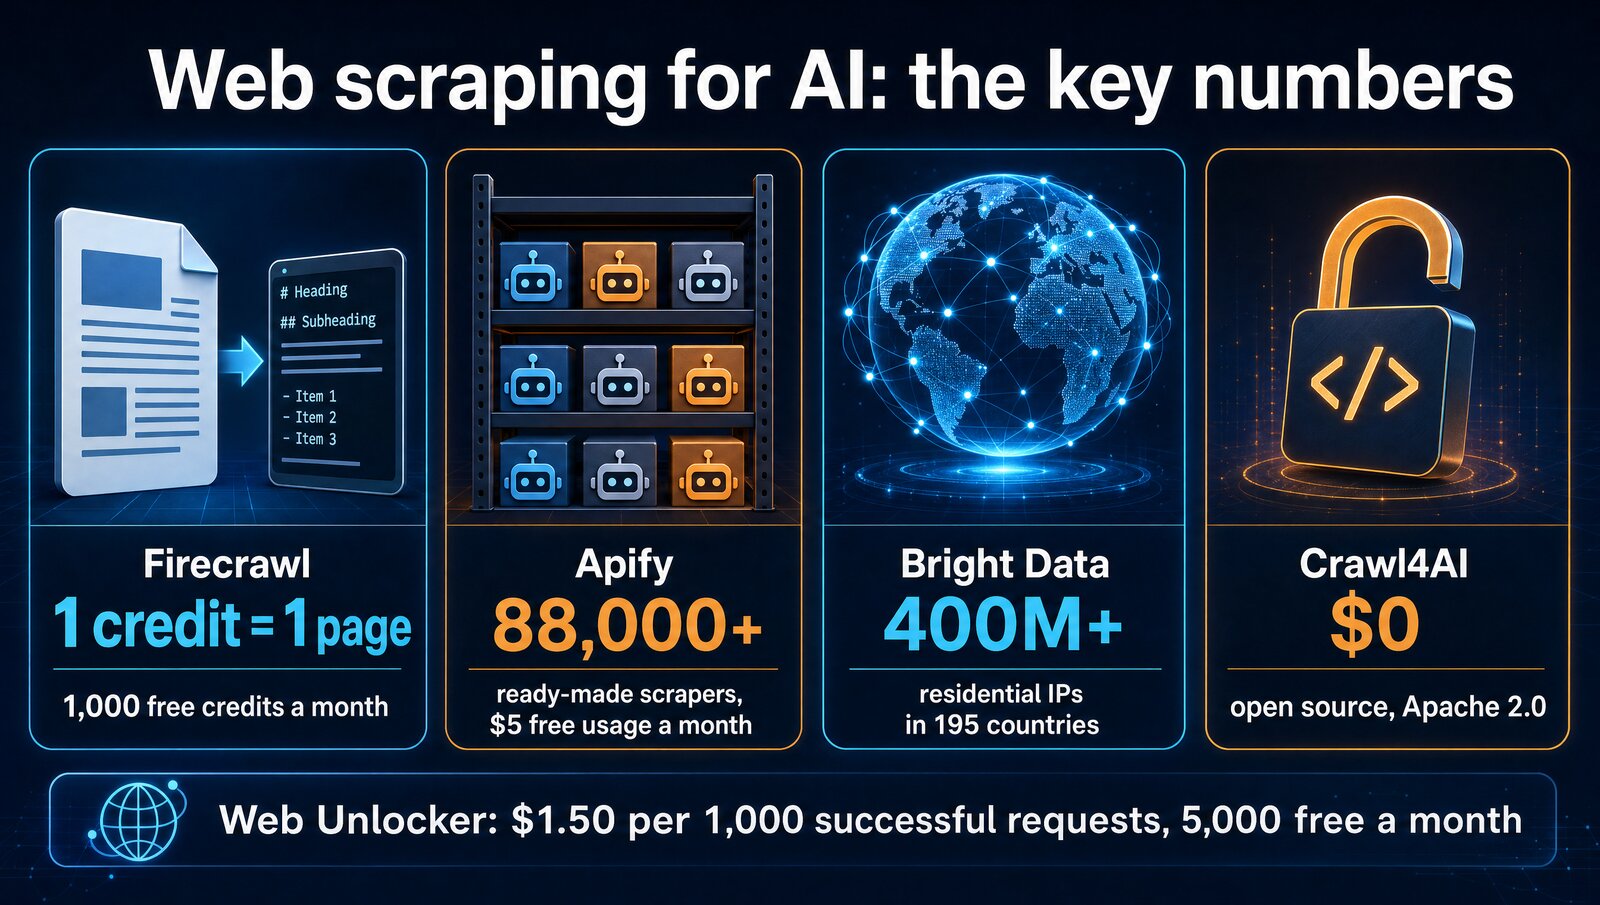
These tools don't compete head to head as much as it seems. Firecrawl reads any page for a model, Apify sells finished scrapers for particular sites, and Bright Data sells the network that gets you through when a site blocks you.
The 4 tools at a glance
Firecrawl- Markdown by default, 1 credit a page
- Hosted MCP server with 27 tools
- 1,000 free credits a month, no card
The catch: the self-hosted version drops key features.
- 88,000+ ready-made scrapers
- Website Content Crawler saves markdown
- $5 of free usage every month
The catch: compute-unit billing is hard to predict.
- 400M+ residential IPs, 195 countries
- Pay only for successful requests
- 5,000 free requests a month
The catch: built and priced for big companies.
- Open source, Apache 2.0
- Clean markdown with tables and code intact
- Runs with pip or Docker, MCP included
The catch: you handle blocks yourself.
Prices at a glance
Prices checked October 15, 2026, on each company's own pricing page.
| Service | Free plan | Paid from | Markdown output | MCP server | Self-host |
|---|---|---|---|---|---|
| Firecrawl | 1,000 credits/mo, no card | $16/mo billed yearly ($19 monthly) for 5,000 credits | Default, 1 credit/page | Yes, hosted, 27 tools | Yes, AGPL-3.0, fewer features |
| Apify | $5 usage/mo | $17/mo billed yearly ($19 monthly) | Via Website Content Crawler | Yes, hosted | Crawlee library only |
| Bright Data | 5,000 requests/mo (Web Unlocker, MCP) | $1.50 per 1,000 requests, pay as you go | Via MCP scrape_as_markdown | Yes, hosted, MIT | No |
| Crawl4AI | Unlimited self-hosted | Cloud from $10/mo | Default | Yes | Yes, Apache 2.0 |
What each one can do
| Feature | Firecrawl | Apify | Bright Data | Crawl4AI |
|---|---|---|---|---|
| Free plan | ✓ | ✓ | ✓ | ✓ |
| Markdown by default | ✓ | Via crawler | Via MCP | ✓ |
| MCP server | ✓ | ✓ | ✓ | ✓ |
| Handles anti-bot blocks | Cloud only | Via proxies | ✓ | ✗ |
| Ready-made scrapers for specific sites | – | ✓ | Datasets | – |
| Simple per-page or per-request pricing | ✓ | ✗ | ✓ | – |
| Self-hosting | Limited | Crawlee only | ✗ | ✓ |
– means the company hasn't said.
Firecrawl: the best scraping API for LLMs
Firecrawl was built for AI from day one. Send it a URL and you get clean markdown back, or HTML, screenshots and structured JSON. It renders JavaScript, can click, scroll and type before it extracts, and can crawl a whole site, map its URLs or search the web.
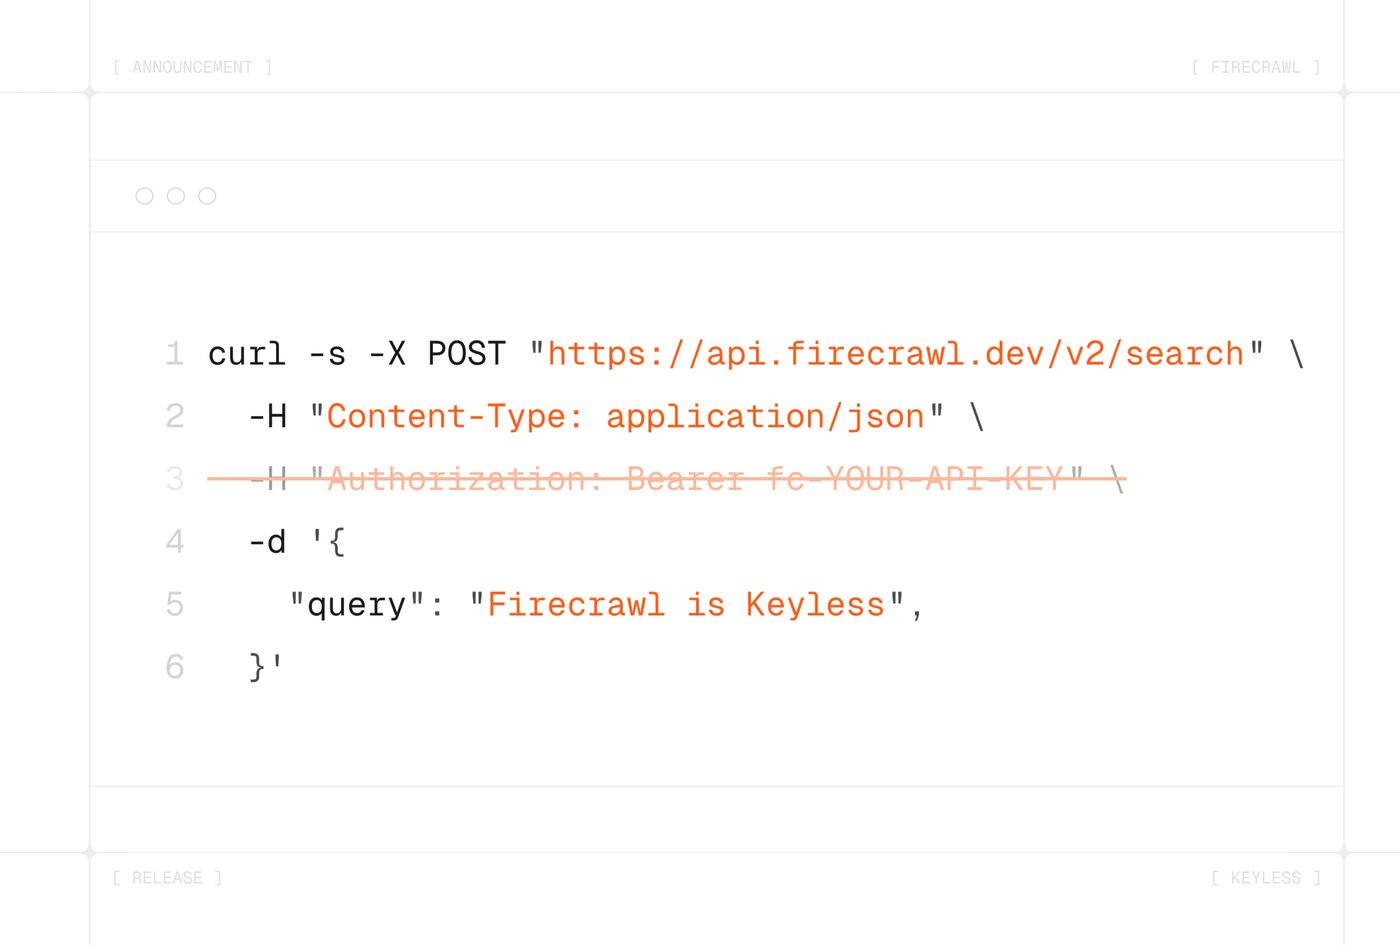
Scrape, crawl and map cost 1 credit per page, and search costs 2 credits per 10 results. Standard is $83 a month billed yearly for 100,000 credits and Growth is $333 for 500,000. Its hosted MCP server registers 27 tools, and a keyless free tier exposes scrape, search and parse with no API key. See our best Claude Code MCP servers guide for where it fits.
The catch: the open-source version is AGPL-3.0, and Firecrawl's docs say its Fire-engine anti-bot layer, screenshots, page actions and the Agent endpoint need Firecrawl Cloud or a separate service.
Apify: the biggest library of ready-made scrapers
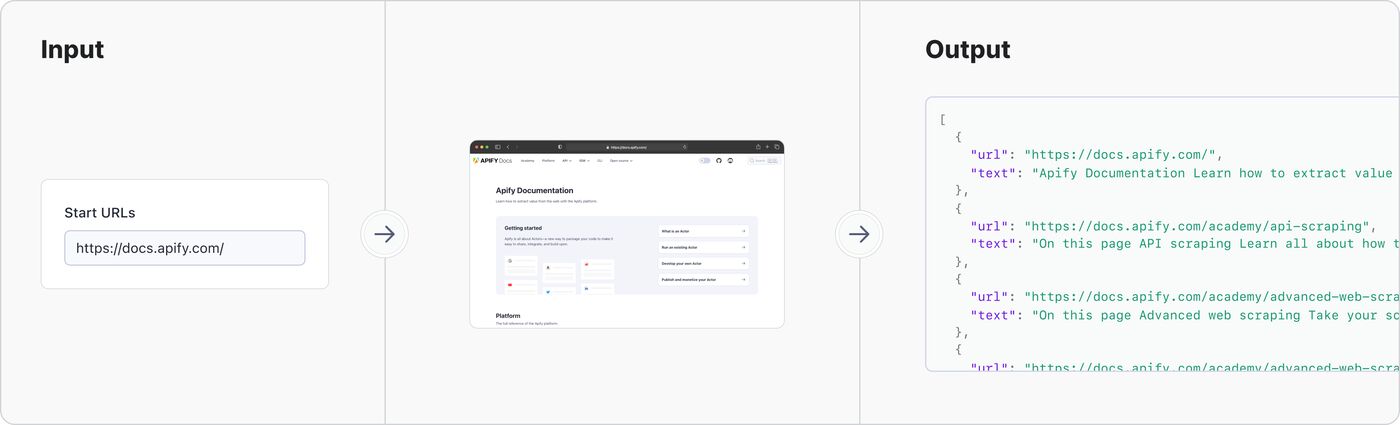
Apify is a platform for running scrapers, which it calls Actors, and its Store lists more than 88,000 of them. Need Google Maps listings or Amazon products? Someone has probably built and maintained an Actor for it. The Apify MCP server at mcp.apify.com lets an agent search the Store and run any Actor by name.
For AI, the key Actor is Website Content Crawler. It strips navigation, footers and cookie banners, saves clean markdown, and connects to LangChain, LlamaIndex, Pinecone and Qdrant. Apify estimates about $0.20 per 1,000 pages over raw HTTP and $0.50 to $5 per 1,000 with a headless browser. Scale is $199 a month and Business is $999.
The catch: billing is in compute units, so bills are harder to predict than per-page credits. Store Actors come from many developers and quality varies, and on Free, access stops for the month once your $5 is gone.
Bright Data: the heavyweight for blocked sites
Bright Data started as a proxy network, and that's still its edge. It says it runs more than 400 million residential IPs in 195 countries, and sells Web Unlocker, which handles blocks, CAPTCHAs and retries, plus a Scraping Browser, a SERP API and datasets.
The Web Unlocker Scale plan is $499 a month for 383,000 requests, and Scraping Browser is $8 per GB. Residential proxies list at $8 per GB, currently shown at $4 per GB pay as you go. Its MIT-licensed MCP server has 32 tools, and scrape_as_markdown returns any URL as markdown with bot protection handled.
The catch: the lineup is confusing, nothing is self-hostable, and outside the MCP server the core products return HTML, JSON or CSV rather than LLM-ready markdown.
What about Crawl4AI, Jina Reader, ScrapingBee and Exa?
Crawl4AI is the best free Firecrawl alternative. It's built on Playwright with Chromium, Firefox and WebKit, and both the self-hosted server and Crawl4AI Cloud offer MCP. The cloud includes 1,000 free credits a month.
Jina Reader is the fastest way to try LLM-ready scraping: put r.jina.ai in front of any URL. No key is needed at 20 requests a minute, and a free key raises that to 500 with 10 million tokens. Great for prototypes, not whole-site crawls.
ScrapingBee now offers a markdown scraper, from $19 a month for 75,000 credits. Exa is a search engine for AI rather than a scraper: search is $4 per 1,000 requests, contents $1 per 1,000, with $10 a month in free credits and a hosted MCP server. For cheaper proxies and scraping APIs, see our Bright Data alternatives.
Which one should you use?
The verdict
Firecrawl is the best web scraping API for AI in 2026. Markdown is the default, the credits are easy to predict, and its MCP server is the most complete for coding agents. Apify wins when someone has already built the scraper you need, Bright Data wins when sites block everything else, and Crawl4AI is the open-source pick.
FAQ
What is the best web scraping API for AI?
Firecrawl is the best web scraping API for AI in 2026. It returns clean, LLM-ready markdown by default at 1 credit per page, renders JavaScript, crawls whole sites and has a hosted MCP server. The free plan includes 1,000 credits a month with no card required.
Is Firecrawl better than Apify?
Firecrawl is better for turning any web page into markdown for an LLM, with simpler per-page pricing. Apify is better when you need structured data from a specific site, because its Store lists more than 88,000 ready-made scrapers. Apify bills by compute units, which makes costs harder to predict.
Bright Data vs Apify: which is better?
Bright Data is better for heavily protected sites at large scale, thanks to its Web Unlocker and a residential network it says has more than 400 million IPs. Apify is better for smaller teams that want ready-made scrapers and a $5 monthly free allowance. Both offer hosted MCP servers.
What are the best Firecrawl alternatives?
Crawl4AI is the best free, open-source Firecrawl alternative, and Jina Reader is the quickest way to get markdown from a URL. Apify and Bright Data are the strongest paid alternatives for specific sites and for blocked sites. Exa is the pick if your agent needs AI search rather than scraping.
Can I self-host Firecrawl?
Yes. Firecrawl is open source under AGPL-3.0 and can be self-hosted. Its docs say the self-hosted version lacks the Fire-engine anti-bot layer, screenshots, page actions and the Agent endpoint, which need Firecrawl Cloud or a separate service.